On this article, you’ll be taught what voice brokers are, how they differ from text-based AI programs, and the way to construct your data from the bottom up utilizing a structured seven-stage roadmap.
Matters we’ll cowl embrace:
- The core three-stage pipeline that defines how voice brokers work, from speech-to-text by language processing to text-to-speech.
- The important thing methods voice agent growth differs from constructing text-based brokers, together with latency, dialog design, and compounding errors.
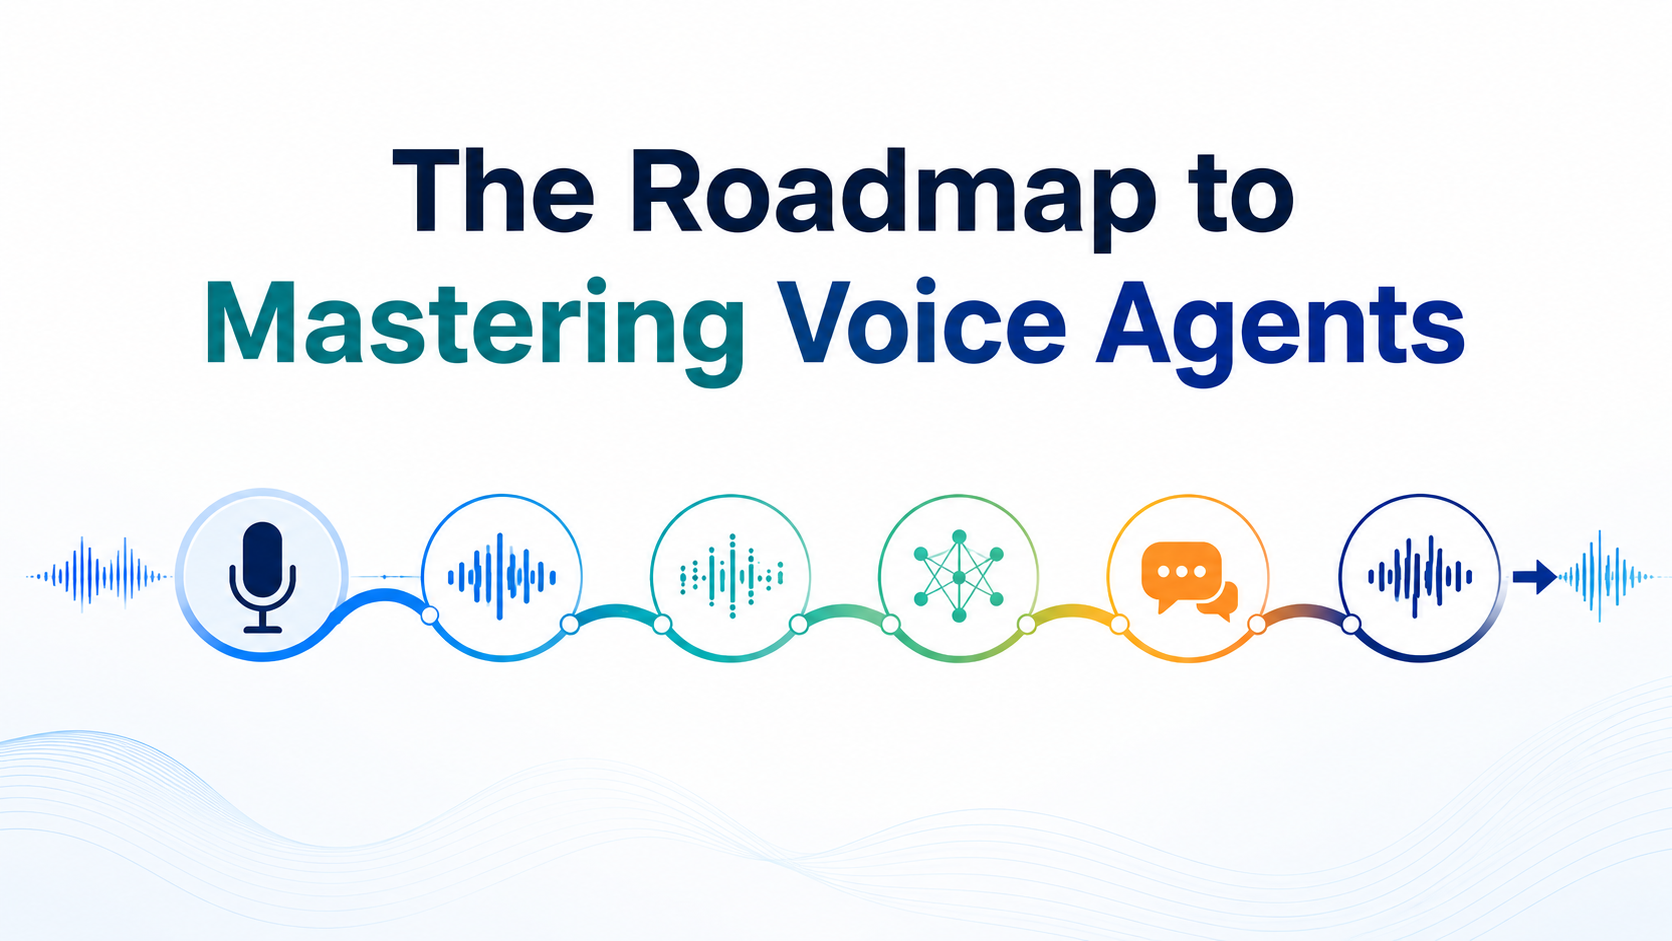
- A seven-stage studying roadmap that takes you from foundational ideas by deployment and superior specializations.
Introduction
Voice interfaces are not a novelty. They’re rapidly turning into the usual approach folks work together with AI programs, from customer support bots to healthcare assistants to sensible house gadgets. When you’ve hung out studying about giant language fashions (LLMs) or text-based brokers, you have already got a powerful basis. Voice brokers construct on lots of the similar concepts however add one essential layer: the flexibility to pay attention, perceive, and reply in pure spoken language.
This tutorial introduces what voice brokers are, how they differ from text-based programs, and lays out a transparent studying roadmap for constructing your data from the bottom up. By the tip, you’ll have a transparent image of what it takes to go from idea to working voice system.
What Is a Voice Agent?
A voice agent is an AI system that communicates by spoken language. It listens to what an individual says, interprets the that means, decides the way to reply, and delivers that response as speech in a approach that feels pure and conversational.
Consider a voice agent as a textual content agent with two further layers wrapped round it. On one facet, audio is available in and should be transformed to textual content earlier than the agent can course of it. On the opposite facet, textual content should be transformed again to audio earlier than the agent can converse its response.
This construction offers voice brokers three distinct phases that textual content brokers don’t require:
Speech-to-Textual content (STT): The system listens to a person’s spoken phrases and transcribes them into textual content. That is typically referred to as Automated Speech Recognition (ASR).
Language Understanding and Response: The transcribed textual content is handed to an LLM or related reasoning system. This stage works nearly identically to a textual content agent. The mannequin interprets the enter, retrieves info if wanted, and generates a response.
Textual content-to-Speech (TTS): The textual content response is transformed again into audio and performed to the person by audio system or a telephone line.
These three phases run sequentially and should full rapidly sufficient that the dialog feels pure. Delays of even a second or two could make a voice agent really feel clunky or unresponsive, and that constraint shapes nearly each design determination you’ll make. Which brings us to one of the vital essential questions on voice brokers: how do they really differ from text-based programs?
How Voice Brokers Differ from Textual content Brokers
Now that we’ve an image of the core pipeline, it’s value pausing on what makes voice work genuinely totally different from constructing textual content brokers. When you’re coming from a background in LLMs or chat-based programs, a number of of those variations will reshape the way you method design choices.
Latency issues far more. In a text-based chat interface, a person can tolerate just a few seconds whereas ready for a response to seem. In a spoken dialog, that very same delay seems like a clumsy silence. Voice brokers want to reply rapidly, which impacts each design determination from mannequin choice to pipeline structure.
There isn’t any visible formatting. Textual content responses can use bullet factors, headers, daring textual content, and code blocks to prepare info. Spoken responses can not. A voice agent should talk every little thing by sentence construction, pacing, and phrase alternative alone, so responses must be shorter, cleaner, and structured to make sense when heard somewhat than learn.
Interruptions and turn-taking are pure. In human dialog, folks typically converse over one another, right themselves mid-sentence, or change path. Voice brokers have to deal with these dynamics gracefully, one thing textual content brokers by no means encounter.
Audio high quality impacts efficiency. Background noise, accents, talking velocity, and microphone high quality all affect how precisely the STT layer transcribes speech. A voice agent working in a quiet workplace could carry out very in another way from one deployed in a loud retail atmosphere.
Errors compound throughout phases. This final level is particularly value maintaining in thoughts. If the STT layer mishears a phrase, the language mannequin receives incorrect enter and generates a response to the unsuitable query. The TTS layer then speaks that incorrect response aloud. Every stage within the pipeline is a possible level of failure, and errors in early phases have an effect on every little thing that follows.
Collectively, these constraints make voice agent growth a self-discipline that rewards cautious, end-to-end considering.
Why Voice Brokers Are Price Studying
Given these added complexities, you may wonder if voice brokers are value the additional effort. The reply turns into clear whenever you take a look at the place the sphere is headed. The sensible purposes are increasing quick, and industries throughout the board are actively deploying them.
- Customer support: Automating name heart interactions for banking, insurance coverage, utilities, and retail.
- Healthcare: Dealing with appointment scheduling, symptom triage, and drugs reminders.
- Training: Offering conversational tutoring and language studying observe.
- Accessibility: Serving customers who can’t simply learn or sort attributable to visible impairments or motor limitations.
- Good gadgets: Powering assistants in houses, autos, and wearables.
For anybody already working with text-based AI programs, voice agent expertise open doorways to a a lot wider vary of deployment eventualities. And with a transparent roadmap, the trail from foundational understanding to real-world deployment is extra simple than it would seem.
The Roadmap: Constructing Your Voice Agent Information
Studying voice brokers nicely means working by a number of interconnected layers of information. The roadmap beneath strikes from foundational to superior, so you’ll be able to construct understanding progressively somewhat than leaping in on the deep finish. Every stage connects on to the subsequent, and skipping forward tends to create gaps that trigger confusion later.
Stage 1: Understanding the Core Pipeline
Earlier than constructing something, you want a transparent psychological mannequin of the three-stage pipeline: STT, language processing, and TTS. Spend time understanding what occurs at every stage, what can go unsuitable, and the way the phases join to one another.
Key inquiries to reply right here: What codecs does audio knowledge are available in? How do STT fashions deal with noise and accents? What’s phrase error charge and why does it matter? How do TTS programs differ in high quality and expressiveness? Getting comfy with these questions builds the instinct you’ll want for each stage that follows.
Stage 2: Studying the Language Processing Layer
With the pipeline construction in thoughts, the subsequent step is to go deeper on the layer at its heart. If you have already got expertise with LLMs or textual content brokers, this stage will really feel acquainted. The language processing layer in a voice agent works the identical approach as in a textual content agent: a mannequin receives enter, causes about it, and generates a response.
The variations are within the constraints. Responses should be quick and conversational. The mannequin can’t use formatting. It should deal with incomplete or imperfectly transcribed enter gracefully. Understanding immediate engineering for voice-specific constraints is a key talent at this stage, and one which pays dividends all through the remainder of the roadmap.
Stage 3: Exploring Actual-Time and Streaming Architectures
Constructing in your understanding of the pipeline and its language layer, now you can deal with one of the vital distinctive engineering challenges in voice: latency. Normal textual content brokers can afford to attend till a full response is generated earlier than displaying it. Voice brokers typically can’t.
To cut back perceived latency, many voice programs use streaming, the place textual content is distributed to the TTS layer incrementally because the language mannequin generates it somewhat than ready for the whole response. This stage includes understanding how streaming works, what tradeoffs it introduces, and the way to architect a pipeline that delivers quick, fluent responses with out sacrificing accuracy. That is the place the summary pipeline begins to really feel like an actual system.
Stage 4: Finding out Dialog Design
That is the place issues get fascinating, and the place many technically robust builders are stunned. Constructing a voice agent that works technically is just half the problem. Constructing one which customers truly get pleasure from speaking to requires deliberate dialog design.
This self-discipline attracts from linguistics, person expertise analysis, and human components. It covers the way to write prompts and responses that sound pure when spoken, the way to deal with misunderstandings gracefully, the way to design turn-taking logic, and the way to give a voice agent a constant character.
The distinction between a voice agent that feels robotic and one which feels genuinely useful is normally within the dialog design, not the underlying mannequin. You possibly can have a succesful LLM on the core and nonetheless produce a irritating expertise if the dialog design is poor.
Stage 5: Integrating Instruments and Reminiscence
With a well-designed conversational core in place, the subsequent layer is about extending what your agent can truly do. Similar to textual content brokers, voice brokers can name exterior APIs, search for info, or take actions on the planet. A voice agent dealing with customer support calls, for instance, may search for account info, course of a cost, or schedule a callback.
Reminiscence is equally essential. Voice brokers that may keep in mind context throughout a dialog, and even throughout a number of conversations with the identical person, ship a significantly better expertise than people who deal with each interplay as a contemporary begin. That is the place brokers begin to really feel much less like scripts and extra like real assistants.
Stage 6: Deploying and Evaluating
Getting a voice agent into manufacturing introduces a brand new set of concerns that don’t apply to textual content brokers. That you must take into consideration telephony infrastructure if the agent will function over telephone calls, real-time transcription prices at scale, audio encoding codecs, and latency monitoring.
Analysis can also be extra advanced than you may count on. You possibly can’t merely learn a transcript and decide high quality. That you must take heed to recordings, measure activity completion charges, monitor the place conversations break down, and iterate on each the pipeline and the dialog design. This suggestions loop between deployment knowledge and design enhancements is what separates good voice brokers from nice ones.
Stage 7: Advancing into Specialised Matters
As soon as the foundations are strong, a number of superior areas are value exploring. Multilingual voice brokers require further care at each the STT and TTS layers. Emotion detection lets brokers reply in another way based mostly on a person’s tone. Voice cloning and customized voice creation permit organizations to construct branded audio identities. Actual-time interruption dealing with makes conversations really feel genuinely bidirectional.
These subjects construct immediately on every little thing lined within the earlier phases, which is why they reward the affected person, sequential method the roadmap recommends.
The place to Begin
The correct entry level is dependent upon the place you’re ranging from, and it’s value being intentional about this earlier than diving in.
When you’re comfy with LLMs and textual content brokers, begin with Stage 3 after a fast evaluation of Stage 1. Your language processing data is already robust, so deal with what makes voice pipelines totally different structurally.
When you’re newer to AI programs usually, comply with the roadmap so as from Stage 1. Every stage builds on the earlier one, and the development is designed to make every new idea really feel grounded somewhat than summary.
The secret is to deal with voice agent growth as a self-discipline that mixes technical talent with communication design. One of the best voice brokers are each technically practical and genuinely nice to speak to.
Conclusion
Voice brokers lengthen text-based AI programs by including the flexibility to speak by spoken language. The core pipeline (STT, language processing, and TTS) builds on ideas it’s possible you’ll already know, however introduces actual new challenges round latency, dialog design, and audio high quality.
What makes voice agent growth fascinating is exactly this mix: strong engineering fundamentals alongside a considerate method to interplay design. The technical pipeline will get your agent working. The dialog design makes it value speaking to.
The seven-stage roadmap above offers you a structured path from foundational understanding by deployment and superior subjects. Work by the phases so as, check your data at every step, and also you’ll be nicely positioned to construct voice brokers that maintain up in manufacturing.