Google Search has simply up to date its favicon documentation to now specify that Googlebot should be capable to observe redirects from the homepage to the web page the place the favicon is specified. The doc additionally explicitly says that these URLs should not be blocked by robots.txt or different means.
The up to date documentation up to date this one bullet level to say:
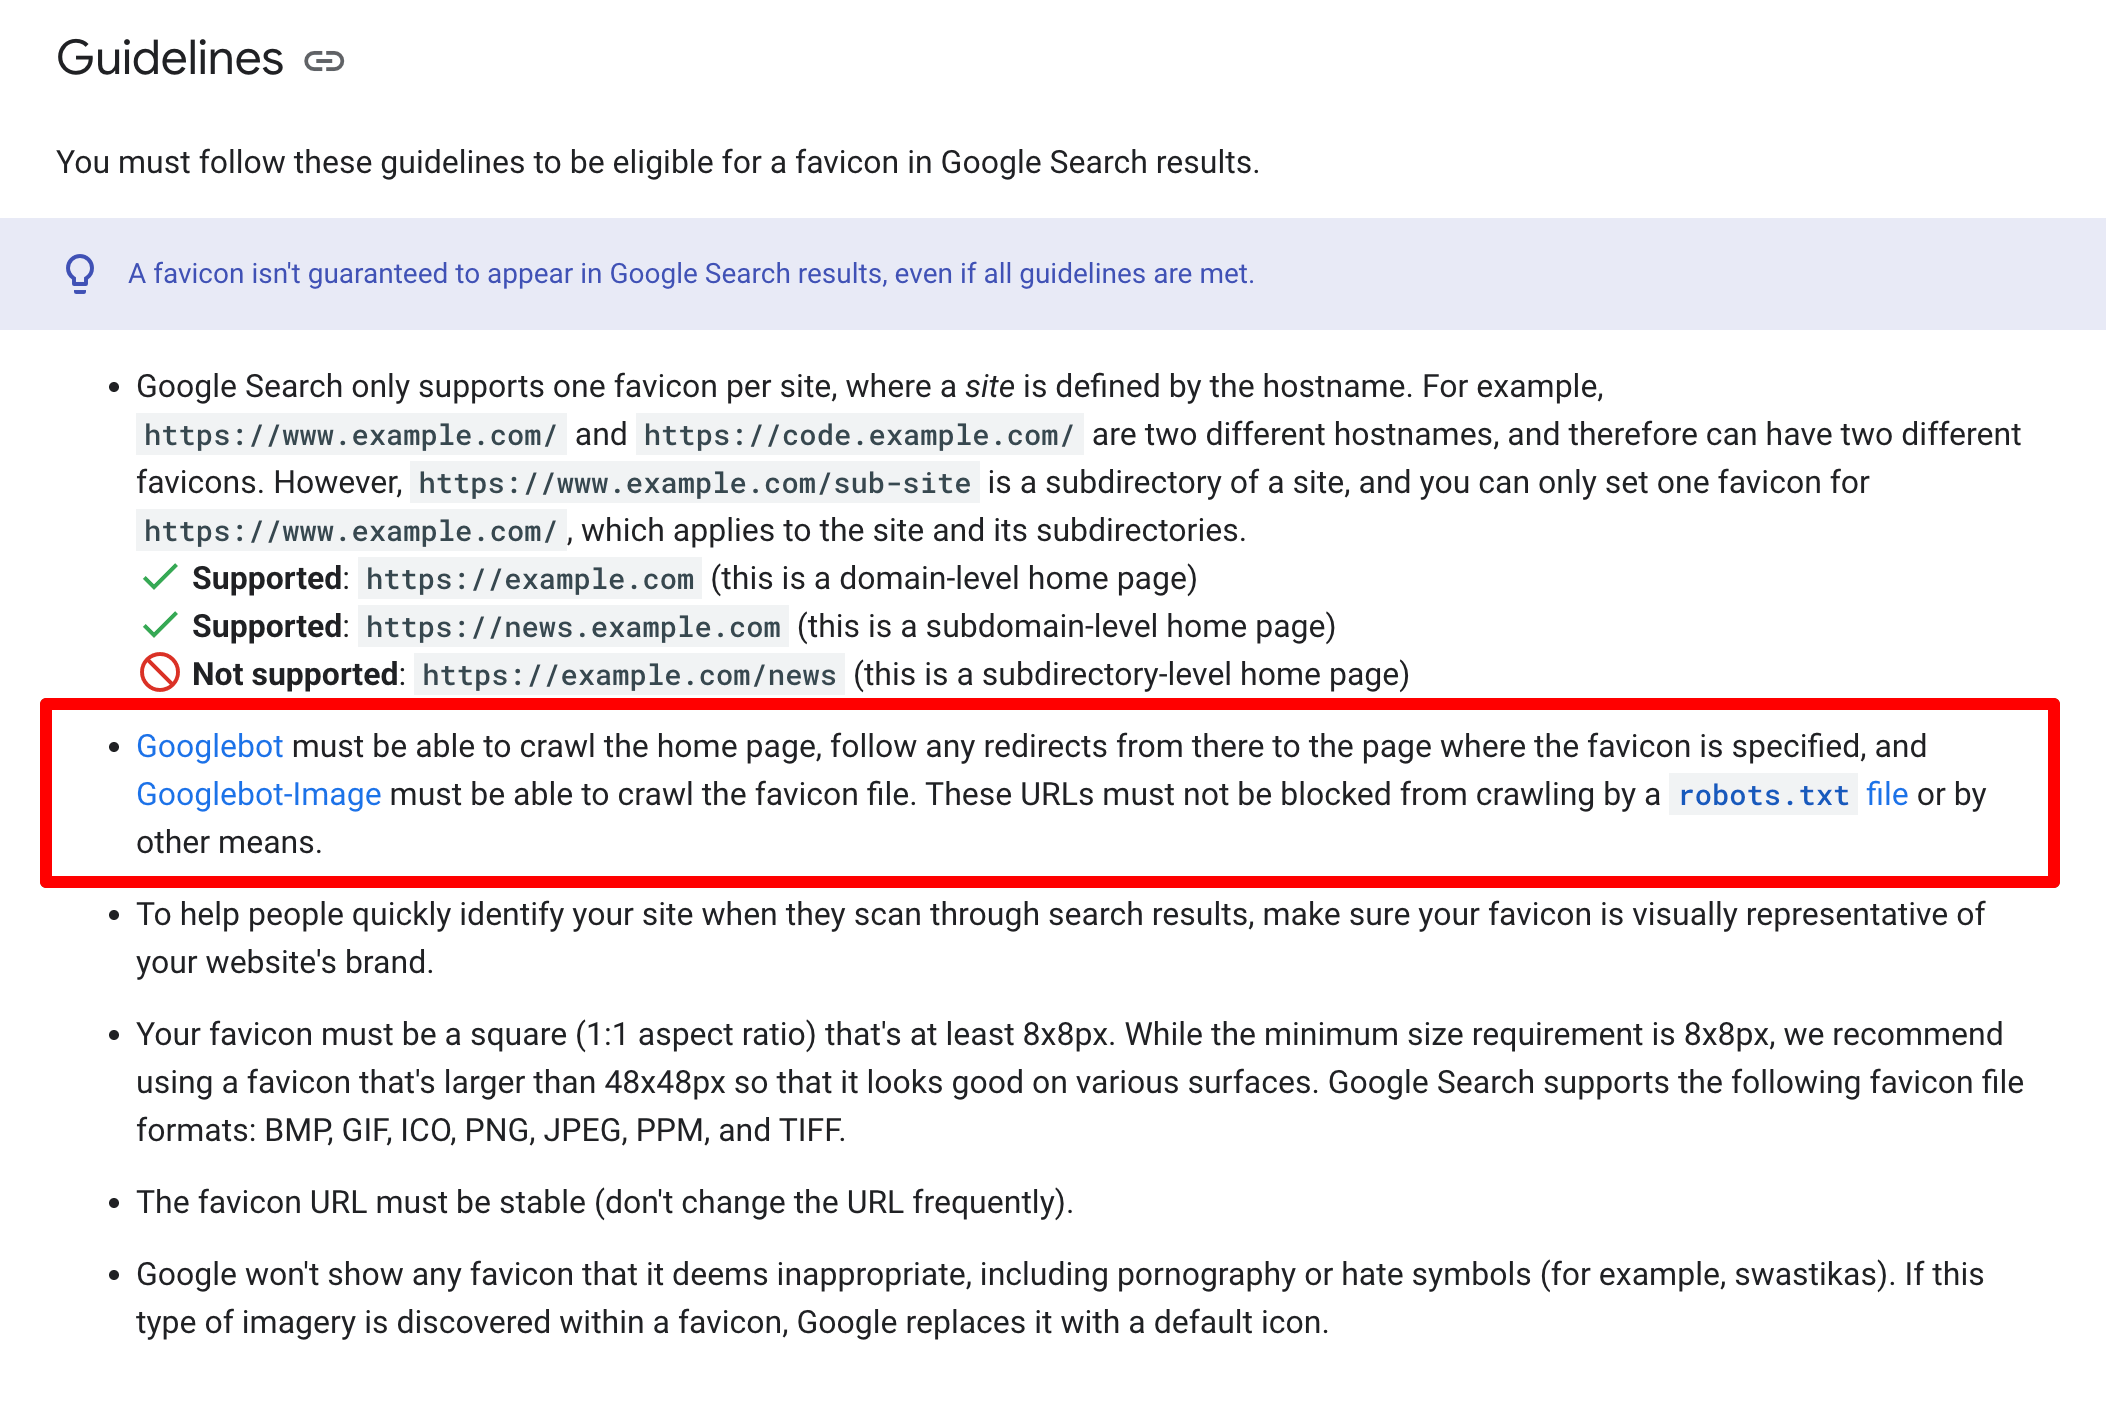
Googlebot should be capable to crawl the house web page, observe any redirects from there to the web page the place the favicon is specified, and Googlebot-Picture should be capable to crawl the favicon file. These URLs should not be blocked from crawling by a robots.txt file or by different means.
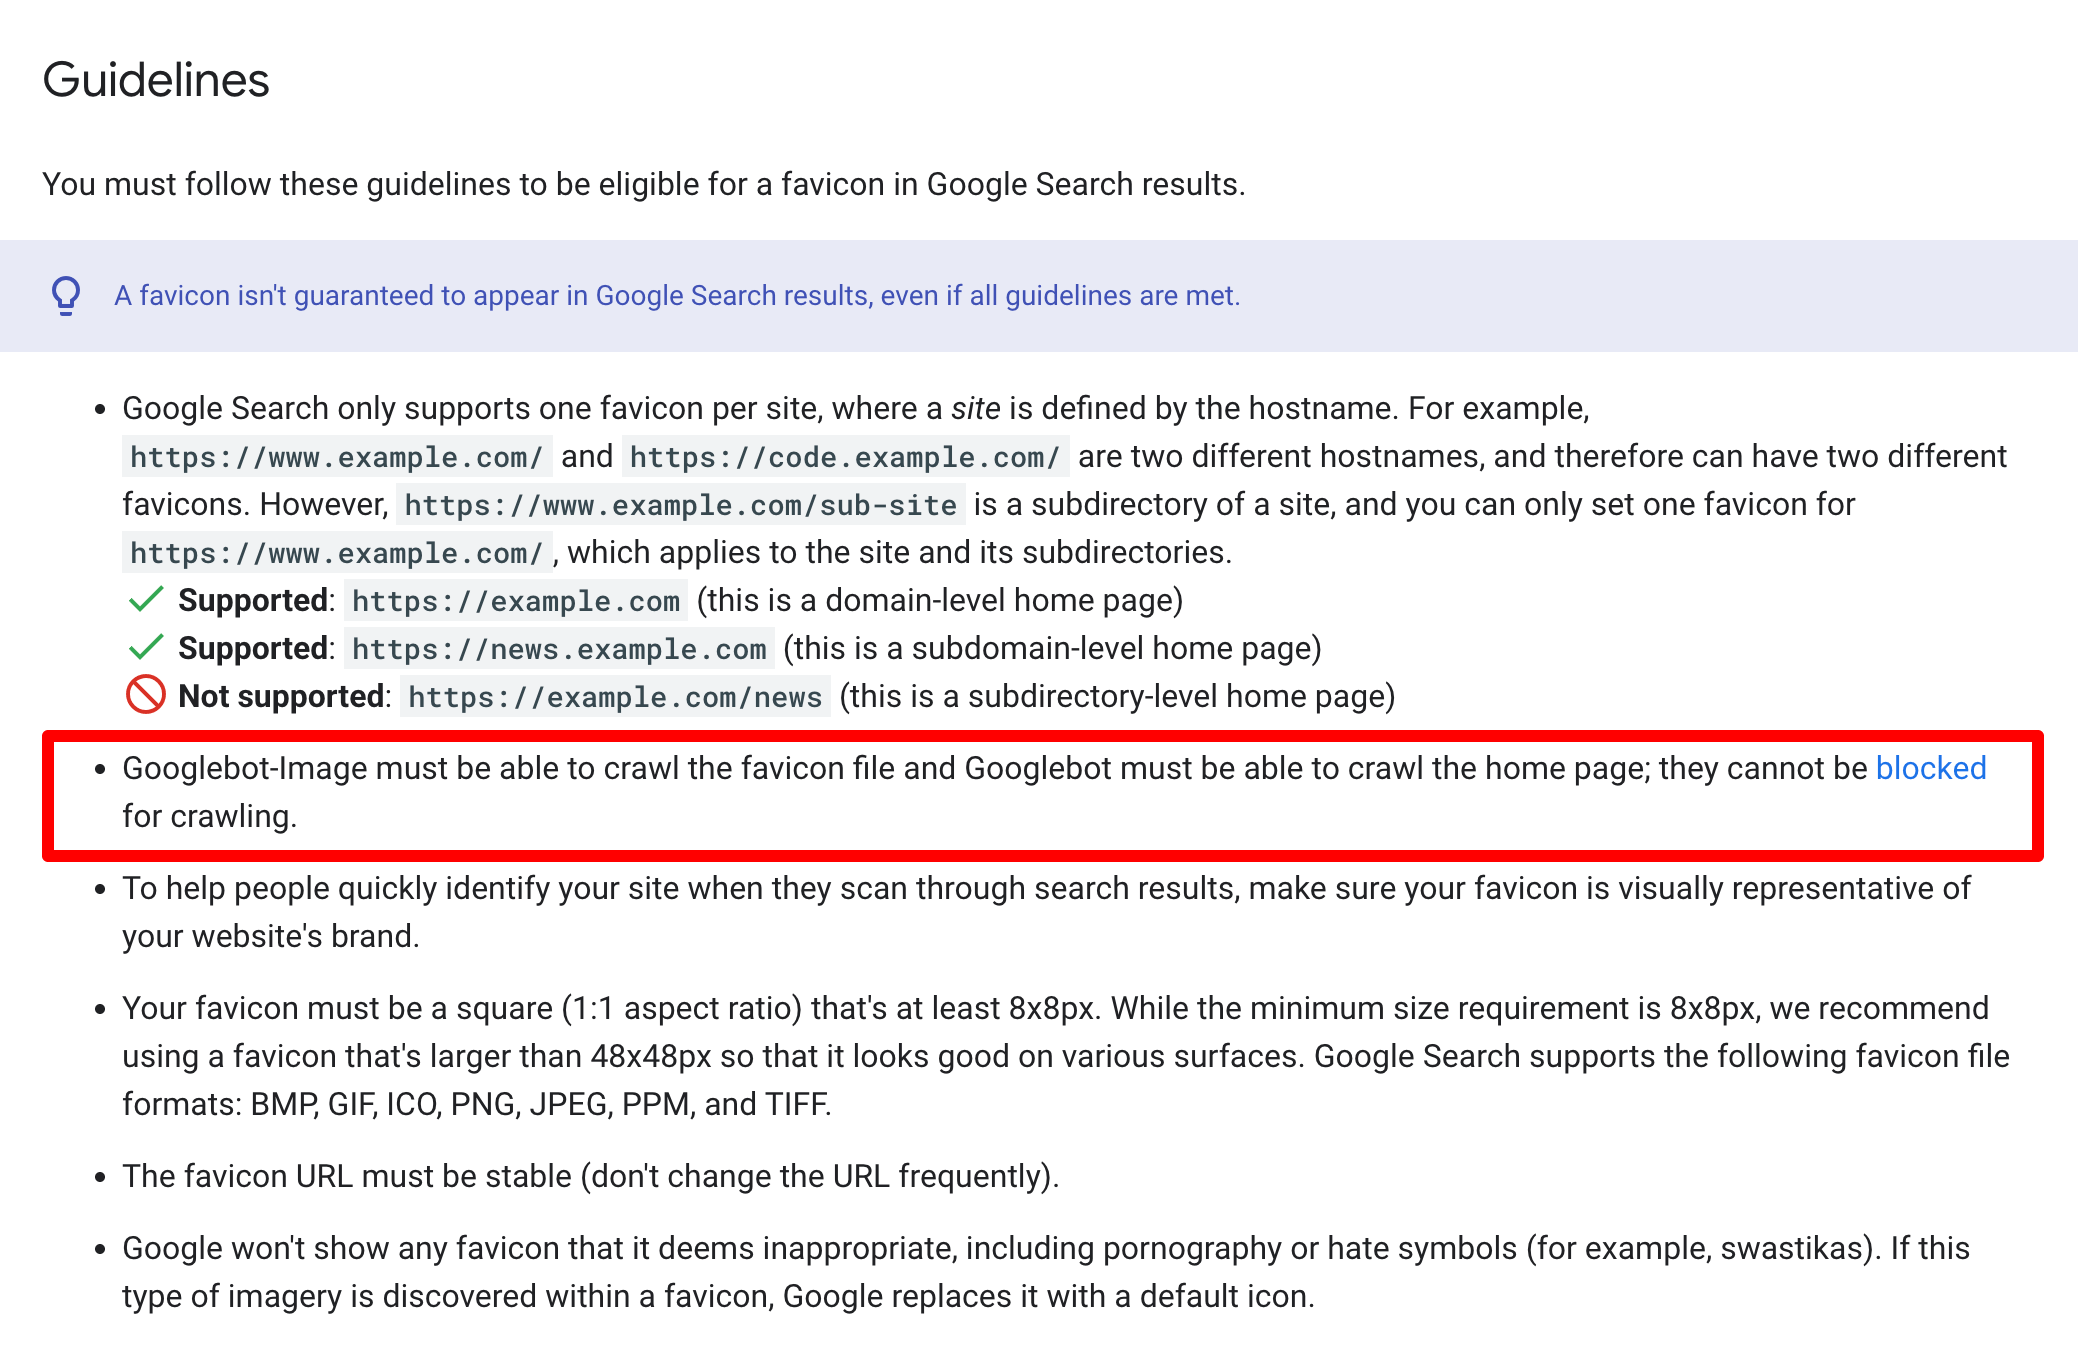
Googlebot-Picture should be capable to crawl the favicon file and Googlebot should be capable to crawl the house web page; they can’t be blocked for crawling.
This appears extra like a clarification than the rest however it’s a good clarification.
Here’s a screenshot highlighting what modified – new doc:
Previous doc:
So ensure to double-check that Google can attain the homepage, observe its redirects, and fetch the favicon.
Discussion board dialogue at LinkedIn.
Replace: John Mueller from Google defined why they made this alteration – due to AI. He wrote:
Enjoyable truth – we did this as a result of we noticed how AI programs did not perceive precisely the way to examine this. In all probability this additionally applies to non-AI’s :-). We tried the change as a immediate, and noticed that it labored significantly better (e.g. “report the rules https://xyz and examine why the favicon on my web site is https://abc not exhibiting up in Google search”). That is even attainable with out marcusunter recordsdata :-).