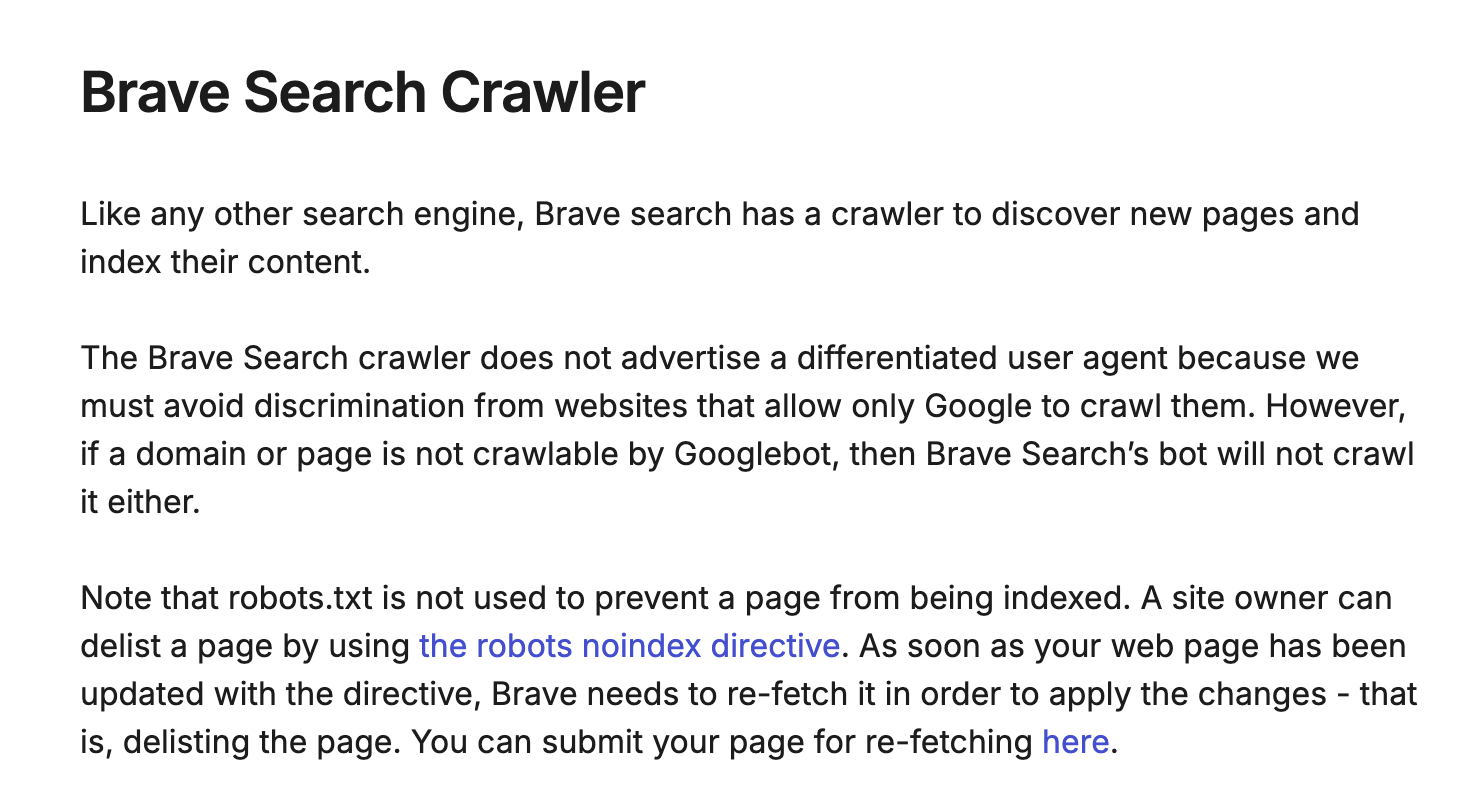
You’ve most likely by no means used Courageous Search. Properly, in a roundabout way. However the AI you ask questions may need, and it may need discovered your web site there. On Nov. 2, the New York Occasions sued Courageous, the corporate behind the Courageous browser and Courageous Search. The Occasions says Courageous copied greater than 30 billion webpages “with out figuring out itself or offering web site homeowners with any mechanism to dam its crawler,” then offered that content material to AI corporations. Courageous hasn’t answered but, so for now these are claims. However why can’t you retain its crawler out with out holding Google out too? Courageous explains that itself, proper there on its assist web page.
Courageous Sells Its Search Index To Cohere, Mistral And Perplexity
Courageous sells entry to its search index to AI corporations, by a product known as the Courageous Search API. When an AI assistant wants one thing current from the online, it doesn’t all the time go and browse the online itself. It could actually pay to go looking another person’s index as a substitute. Courageous’s About web page says the API is “Utilized by a few of the greatest names in AI, together with Cohere, Mistral, Perplexity, and You.com.” Its AI web page says the index holds “over 30 billion pages, with thousands and thousands of recent pages listed every day.”
The Occasions’s criticism opens by naming 5 AI corporations it says Courageous provides: Anthropic, Perplexity, Mistral, xAI and Cohere. None of them is being sued. Claude is the fuzzy one, as a result of the proof is previous. The criticism factors to a 2023 Courageous submit about Anthropic coaching Claude 2. In March 2025 Anthropic added Courageous Search to its record of subprocessors, the skin corporations it makes use of, which TechCrunch reported. The identical week, Simon Willison, a developer who writes a broadly learn weblog about AI instruments, requested Claude to seek for pelican info, and the ten outcomes it cited matched the identical search on Courageous precisely. Whether or not Claude nonetheless makes use of Courageous at this time, I couldn’t verify.
Courageous’s Crawler Doesn’t Have A Title, So You Can’t Block It With out Blocking Google
Web sites resolve which crawlers might learn them in a small file known as robots.txt, and that solely works as a result of crawlers have names. OpenAI and Anthropic every publish the names of theirs, so you may let one firm’s crawlers in and switch the opposite’s away.
Courageous’s assist web page, the one on the high of this text, says its crawler “doesn’t promote a differentiated consumer agent.” In plain phrases, Courageous’s crawler doesn’t put on a reputation tag, and Courageous offers a purpose: Some web sites let Google in and no one else, so a crawler with Courageous’s title on it might get turned away. Courageous says it follows Google’s guidelines as a substitute: no matter Googlebot isn’t allowed to learn, Courageous gained’t learn both.
So you may’t let Google in and preserve Courageous out. You get each, or neither. To get out of Courageous’s index, the identical web page factors you to the noindex tag, which tells Google to drop the web page too. The Occasions calls this Courageous’s “refusal to launch the title of its internet crawler bot.”
My Web site Is In Courageous’s Index, And My Robots.txt Can’t Even Point out It
A Courageous seek for website:nohacks.co on Nov. 3 confirmed 16 of my pages on the primary web page of outcomes, 13 of them articles.
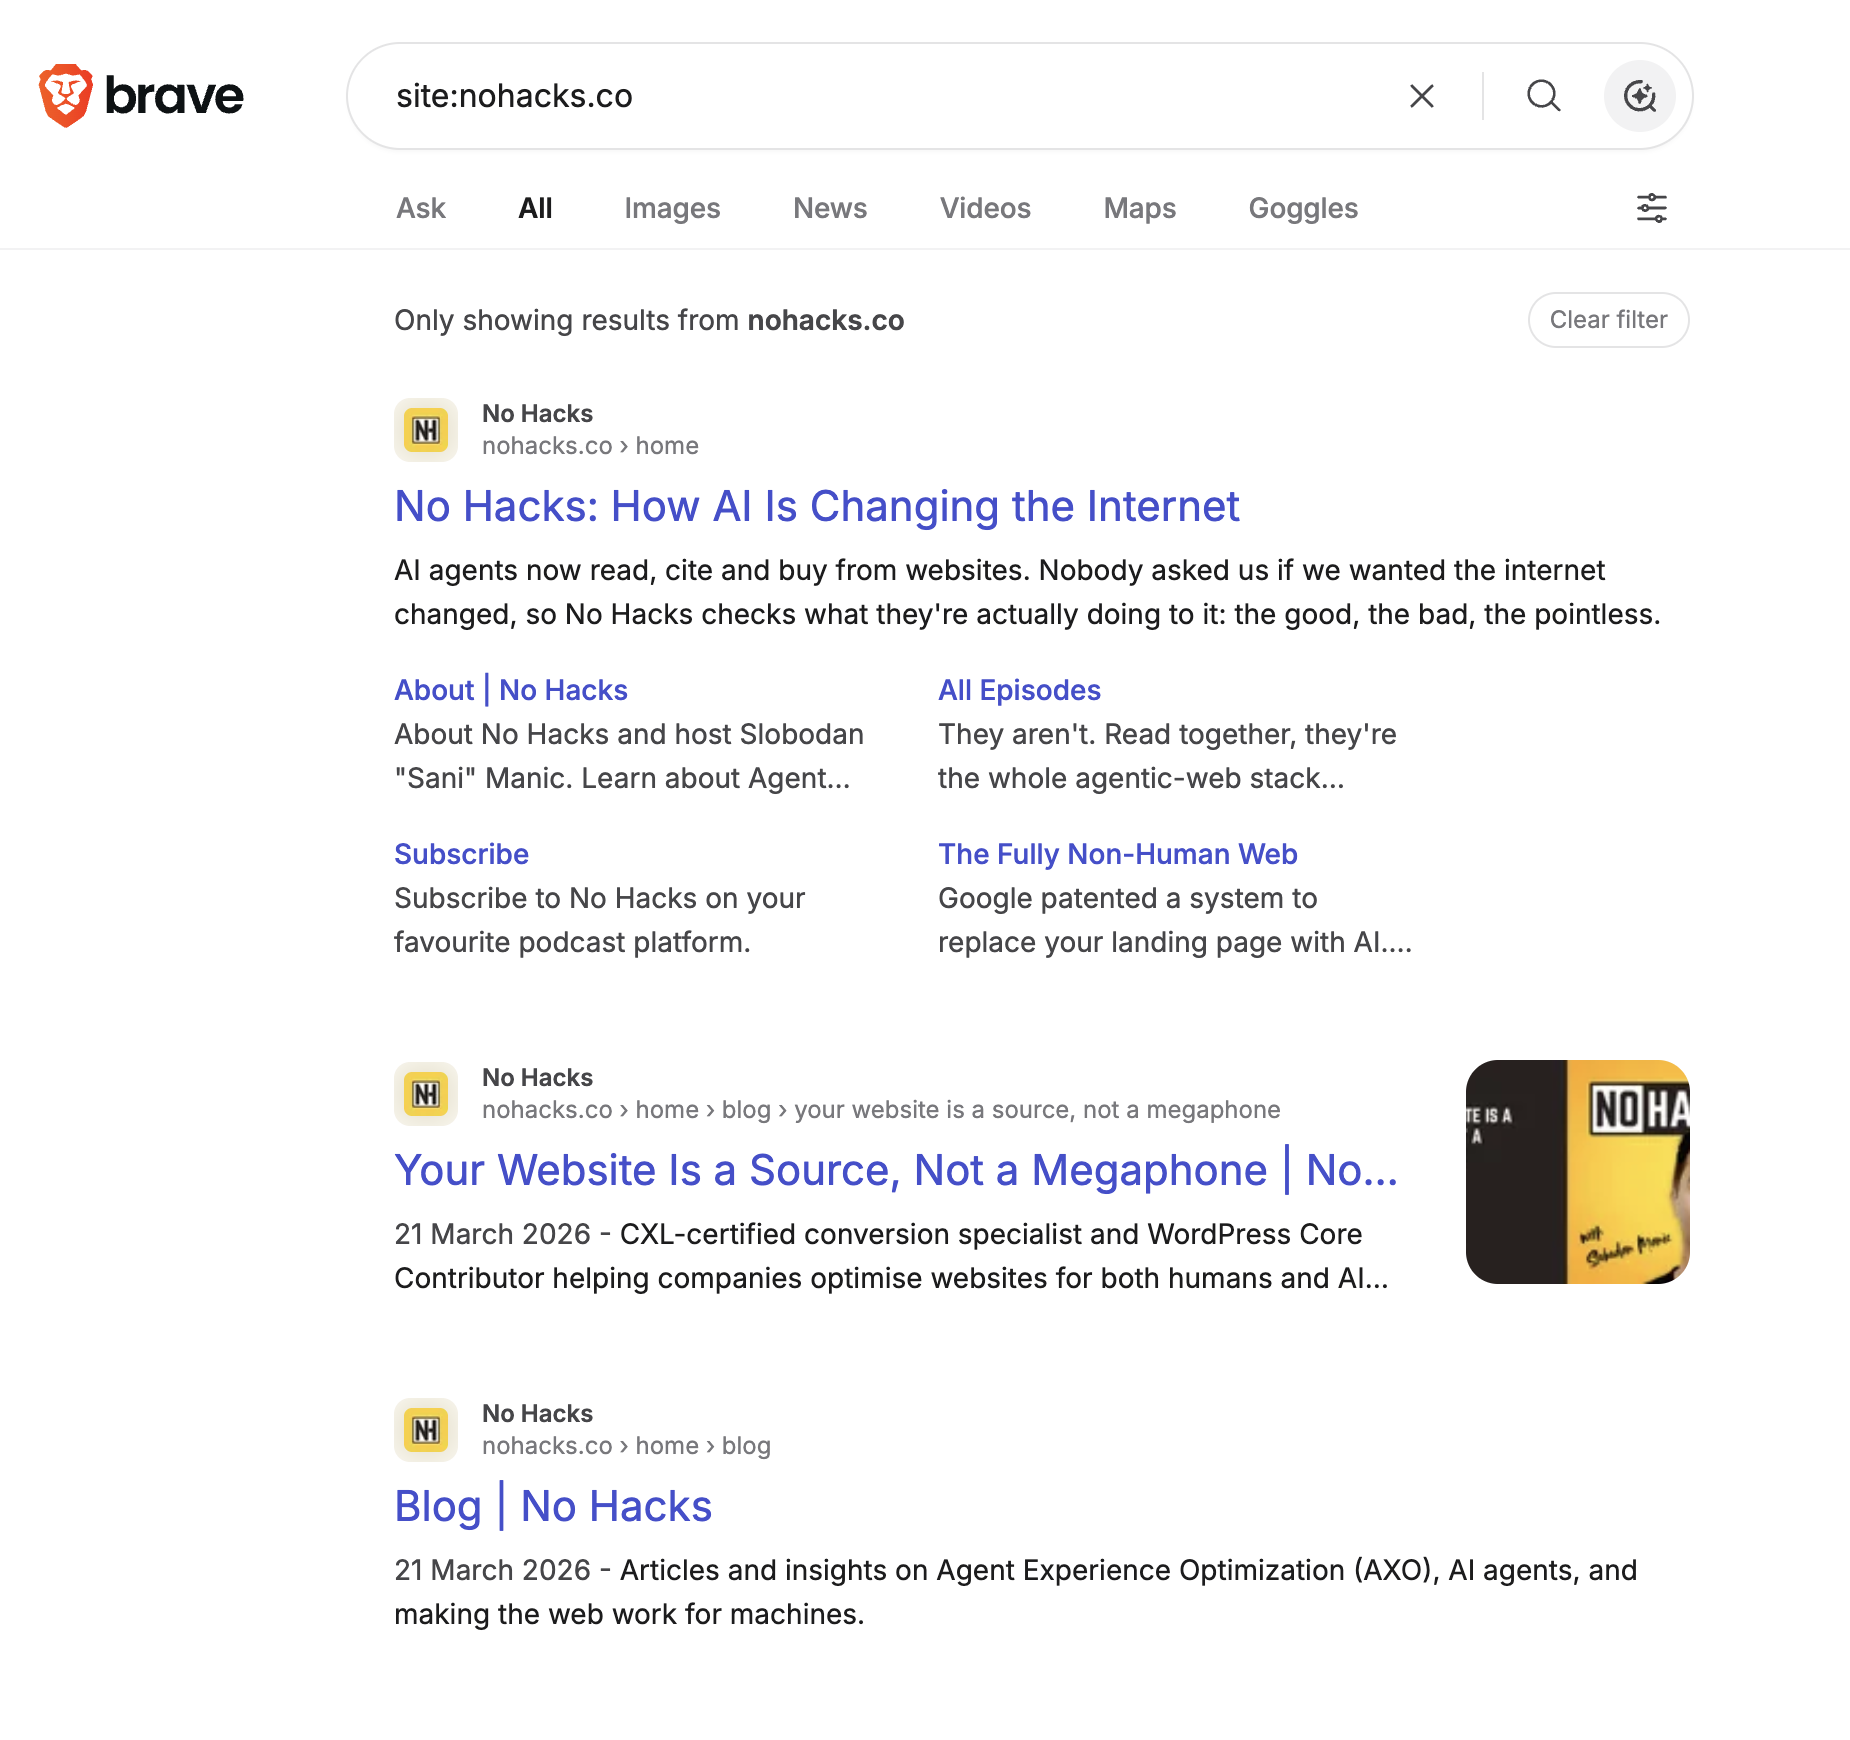
Courageous’s consequence even reveals the homepage description I changed earlier that very same day, so what Courageous serves is a saved copy, not a stay take a look at my web site. My robots.txt names 13 AI bots, from GPTBot to Bytespider, and blocks two of them, Meta’s and ByteDance’s. There’s no line I might add for Courageous. It’s arduous to dam a reputation that doesn’t exist.
Checking yours takes about 30 seconds: go to go looking.courageous.com and sort website: and your area. Every part that reveals up is within the index Courageous sells.
A Search Engine Sends Individuals Again, And An Index Bought To AI Doesn’t Have To
Being in a search engine is a deal each web site understands. Somebody searches, sees your web page, clicks, and lands in your web site. Courageous Search’s strange outcomes work like that, although Courageous has added AI solutions of its personal, known as Ask Courageous, which The Occasions can be suing over.
Promoting the index is a unique deal. The criticism quotes Courageous describing one a part of it, “LLM Context,” as handing over “extracted web page chunks and supply metadata in a form and size that satisfies the wants of an LLM with out want for additional scraping.” So the AI firm will get your web page, already chopped up, and writes a solution from it. Whether or not that reply sends anybody again to you is the AI firm’s name. It isn’t yours, and it isn’t one thing Courageous is promoting. That’s the half that bothers me.
A Court docket Will Determine Whether or not Courageous Can Promote Its Index To AI Corporations
The New York Occasions is claiming copyright infringement and getting round its paywall, amongst different issues, and the Every day Information, the Chicago Tribune and the Orlando Sentinel filed a separate case the identical day. Courageous hadn’t responded to both once I wrote this. It has argued its aspect earlier than, although: when Information Corp despatched it a cease-and-desist, Courageous sued first, saying it was solely indexing the online, which “all search engine operators should do to exist,” and in July 2026 Information Corp sued again, saying Courageous hides its crawlers so publishers can’t detect or block them, Semafor reported. A ruling on The Occasions’s pages gained’t robotically cowl anybody else’s, however it’ll say lots about each web site in that index, and that’s most likely yours too. So I’ll be watching this one.
Extra Sources:
This submit was initially revealed on No Hacks.
Featured Picture: FotoField/Shutterstock