On this article, you’ll discover ways to add a light-weight temporal reasoning layer to a Graph-RAG system in order that it could distinguish contemporary details from stale ones.
Matters we are going to cowl embrace:
- How you can lengthen commonplace subject-predicate-object triples into time-stamped quadruples saved in a easy temporal graph.
- How you can calculate recency weights with exponential decay and use them to rank conflicting details as of a given question date.
- How you can tune the half-life parameter and combine the temporal graph right into a deterministic 3-tiered Graph-RAG retrieval pipeline.
Introduction and Motivation
In a earlier article, Constructing a Deterministic 3-Tiered Graph-RAG System, we addressed the problem of dealing with conflicting data in RAG (Retrieval-Augmented Technology) architectures. Particularly, we constructed a hierarchy to handle conflicting data by giving “contemporary” details prime precedence over less-fresh ones.
All through that journey, a key query arose: how does our graph-based RAG system know precisely what’s contemporary? Normal data graphs deal with details as “timeless,” context-independent SPO (subject-predicate-object) triples, reminiscent of (Firm, HAS_CEO, Alice). This strategy doesn’t fairly match the actual world we dwell in, the place issues are messy and alter continuously: what if Alice switched jobs and is not CEO? Feeding these details to an LLM with out temporal context is the right recipe for hallucinations, leading to complicated or factually incorrect responses.
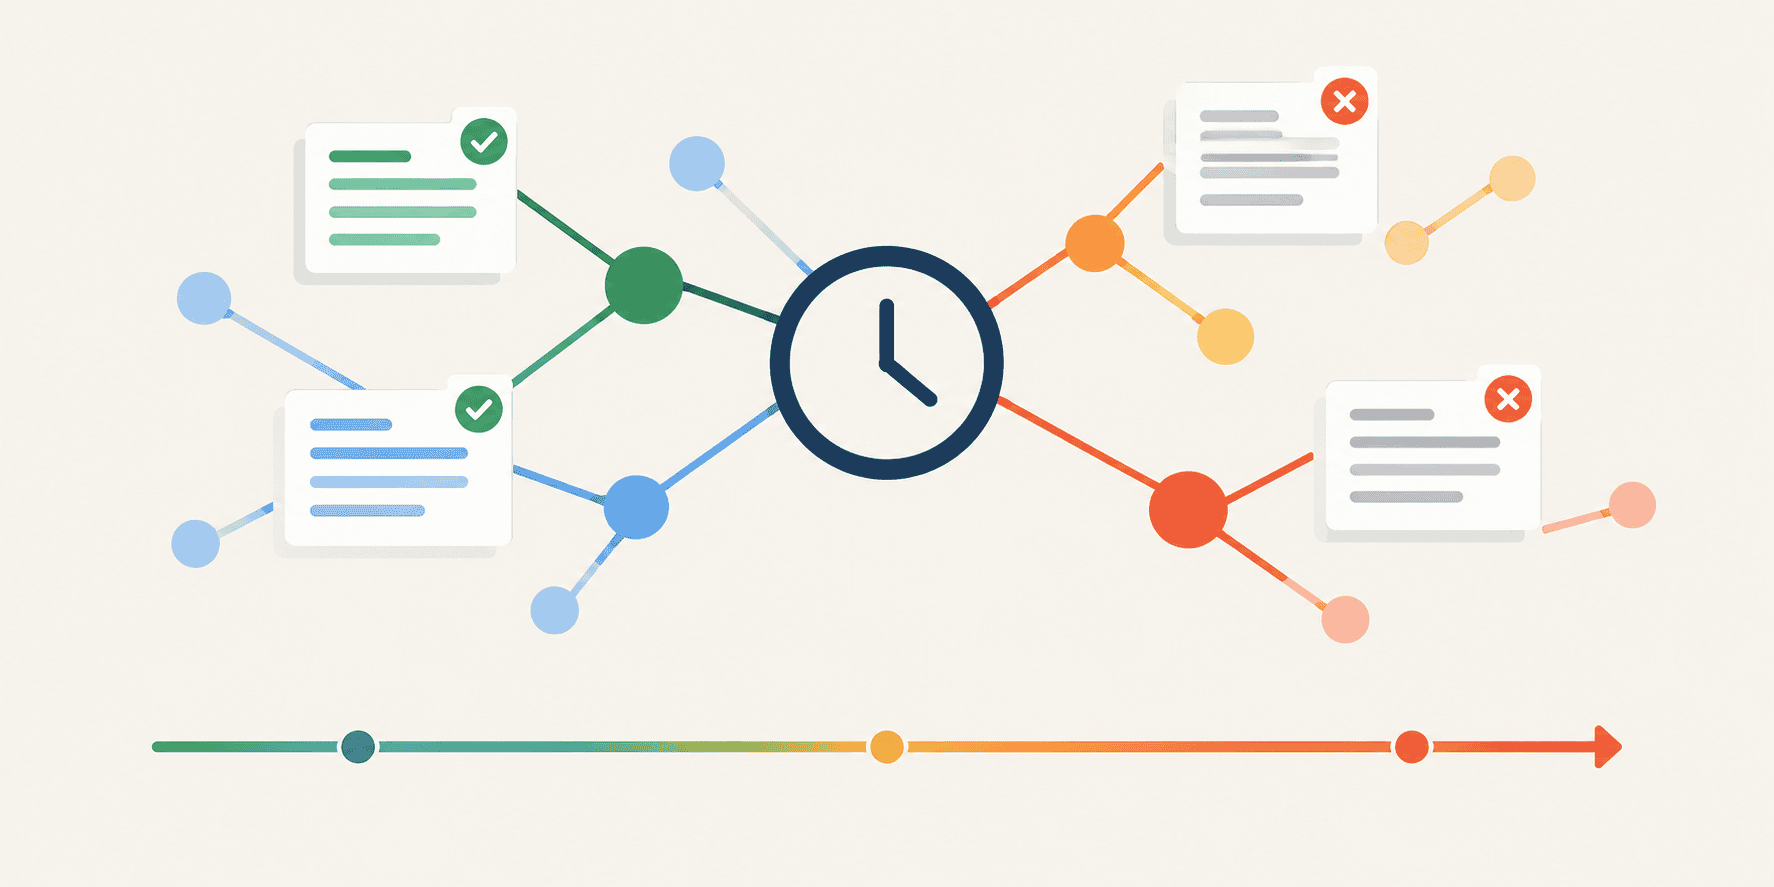
To sort out this problem, this text reveals the key steps to construct a devoted, light-weight temporal reasoning engine for Graph-RAG by way of a couple of easy Python features. We additionally focus on its integration with the 3-tiered Graph-RAG system constructed beforehand. The important thing concept consists of upgrading commonplace triples into time-stamped quadruples and calculating recency weights that point out levels of “truth freshness.”
Prepared? Let’s go!
A New, Temporal Journey, Step by Step
Step one is to increase commonplace SPO triples into “temporal quads,” the place the fourth dimension introduces time, concretely a timestamp: (Topic, Predicate, Object, Timestamp).
The next Python class is outlined to carry our new, prolonged data, additionally referred to as a temporal graph. In case you are working in a pocket book setting, merely paste this code into your first code cell:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 |
import datetime import math
class TemporalGraph: def __init__(self): # Information might be saved on this data base as: Topic -> Predicate -> Listing of (Object, Date) self.knowledge_base = {}
def add_fact(self, topic, predicate, obj, date_string): “”“Provides a time-stamped truth to the graph.”“” # Changing string to a comparable date object fact_date = datetime.datetime.strptime(date_string, “%Y-%m-%d”).date()
if topic not in self.knowledge_base: self.knowledge_base[subject] = {} if predicate not in self.knowledge_base[subject]: self.knowledge_base[subject][predicate] = []
self.knowledge_base[subject][predicate].append((obj, fact_date)) print(f“Added: {topic} {predicate} {obj} (as of {date_string})”)
# Initializing our graph tg = TemporalGraph() |
Now it’s time to populate our newly created temporal graph, tg, following a real-world situation the place details change at gentle pace … effectively, possibly not that quick, however nonetheless quickly! If we have been monitoring the management roles in a tech firm throughout a chaotic week stuffed with adjustments, we may have one thing like:
|
# A timeline of shifting details tg.add_fact(“TechCorp”, “HAS_CEO”, “Alice”, “2021-01-15”) tg.add_fact(“TechCorp”, “HAS_CEO”, “Bob”, “2023-11-17”) tg.add_fact(“TechCorp”, “HAS_CEO”, “Charlie”, “2023-11-19”) tg.add_fact(“TechCorp”, “HAS_CEO”, “Bob”, “2023-11-21”) # Bob got here again!
# Including additionally a static truth for a little bit of distinction tg.add_fact(“TechCorp”, “FOUNDED_IN”, “San Francisco”, “2010-05-01”) |
Output:
|
Added: TechCorp HAS_CEO Alice (as of 2021–01–15) Added: TechCorp HAS_CEO Bob (as of 2023–11–17) Added: TechCorp HAS_CEO Charlie (as of 2023–11–19) Added: TechCorp HAS_CEO Bob (as of 2023–11–21) Added: TechCorp FOUNDED_IN San Francisco (as of 2010–05–01) |
Keep in mind that in an ordinary RAG system, a search like “Who acts because the CEO of TechCorp?” would possible retrieve Alice, Bob, and Charlie, abruptly! Thus, we’d like a mechanism to assign truthfulness weights to details, and it’s less complicated than you may assume.
Calculating recency weights is the important thing to resolving doable conflicts mathematically. We simply desire a mechanism that claims: “hey, this truth is newer than that one, so it’s extra prone to represent as we speak’s fact.” A wise strategy to do that relies on exponential decay, which consists of assigning a half-life time window to details. As an example, if the half-life is ready to at least one yr (12 months), then a truth that’s one yr previous will carry a weight of 0.5. In the meantime, a truth asserted as we speak would carry a weight of 1.0.
These two features are designed to introduce the aforementioned weight scoring logic to our temporal graph:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 |
def calculate_recency_weight(fact_date, query_date, half_life_days=365): “”“ Calculates a rating between 0 and 1 based mostly on how previous the very fact is. Utilizing exponential decay: weight = (0.5) ^ (age_in_days / half_life) ““” age_in_days = (query_date – fact_date).days
# If the very fact is from the longer term relative to our question, it’s capped at 1.0 if age_in_days < 0: return 1.0
weight = 0.5 ** (age_in_days / half_life_days) return spherical(weight, 4)
def query_temporal_graph(graph, topic, predicate, as_of_date_str, half_life_days=365): “”“Queries the graph and ranks solutions by their temporal weight.”“” query_date = datetime.datetime.strptime(as_of_date_str, “%Y-%m-%d”).date()
attempt: details = graph.knowledge_base[subject][predicate] besides KeyError: return f“No data discovered for {topic} -> {predicate}”
scored_results = [] for obj, fact_date in details: # We solely contemplate details that occurred ON or BEFORE our question date if fact_date <= query_date: weight = calculate_recency_weight(fact_date, query_date, half_life_days) scored_results.append({ “reply”: obj, “date”: fact_date.strftime(“%Y-%m-%d”), “weight”: weight })
# Sorting by weight (highest/freshest first) scored_results.type(key=lambda x: x[‘weight’], reverse=True) return scored_results |
Lastly, we’re ready to see all of it in motion. We are going to end by displaying an instance that queries our graph. Temporal reasoning acts as a form of “time journey” at execution time: if we added code to persist our details after which requested who the CEO was a couple of days later, the mechanism we applied would merely modify its weights on the fly:
|
print(“— Question 1: Who’s the CEO as of Nov 18, 2023? —“) results_past = query_temporal_graph(tg, “TechCorp”, “HAS_CEO”, “2023-11-18”) for res in results_past: print(f“Candidate: {res[‘answer’]} | Truth Date: {res[‘date’]} | Confidence Weight: {res[‘weight’]}”)
print(“n— Question 2: Who’s the CEO as of Dec 01, 2023? —“) results_present = query_temporal_graph(tg, “TechCorp”, “HAS_CEO”, “2023-12-01”) for res in results_present: print(f“Candidate: {res[‘answer’]} | Truth Date: {res[‘date’]} | Confidence Weight: {res[‘weight’]}”) |
Outcomes:
|
—– Question 1: Who is the CEO as of Nov 18, 2023? —– Candidate: Bob | Truth Date: 2023–11–17 | Confidence Weight: 0.9981 Candidate: Alice | Truth Date: 2021–01–15 | Confidence Weight: 0.1396
—– Question 2: Who is the CEO as of Dec 01, 2023? —– Candidate: Bob | Truth Date: 2023–11–21 | Confidence Weight: 0.9812 Candidate: Charlie | Truth Date: 2023–11–19 | Confidence Weight: 0.9775 Candidate: Bob | Truth Date: 2023–11–17 | Confidence Weight: 0.9738 Candidate: Alice | Truth Date: 2021–01–15 | Confidence Weight: 0.1362 |
As one may anticipate, working the primary question offers us Bob as the highest reply with an virtually full weight: Charlie doesn’t even seem, as he hadn’t been appointed at that time! In the meantime, working the second question reveals a caveat: maybe the 365-day half-life window is simply too lengthy, because it takes a complete yr for details to lose 50% of their relevance. Thus, in a frenetic week stuffed with organizational adjustments, we will see that though Bob is once more the highest reply, he’s very carefully adopted by Charlie and even by Bob’s personal prior appointment. The fast repair consists of adjusting the half_life_days parameter, for example, by altering it from 365 to 7. Attempt it your self and revel in the brand new outcomes!
Wrapping Up
Now that we have now constructed this mechanism to take temporal graph data into consideration, how may it’s built-in into the deterministic 3-tiered structure constructed within the earlier, associated article? When the consumer sends a immediate to the LLM within the RAG system, you’ll desire a retriever that not solely fetches texts: as a substitute, it ought to run the question in opposition to the temporal graph, type details by their confidence weight, and go solely the top-weighted one (or, at most, a small ranked listing) into the immediate’s context. This has the potential to take away the LLM’s must guess which truth is probably the most present one: that subject is sorted out even earlier than the ultimate immediate reaches the mannequin.