• About Us
  • Privacy Policy
  • Disclaimer
  • Contact Us
AimactGrow
  • Home
  • Technology
  • AI
  • SEO
  • Coding
  • Gaming
  • Cybersecurity
  • Digital marketing
No Result
View All Result
  • Home
  • Technology
  • AI
  • SEO
  • Coding
  • Gaming
  • Cybersecurity
  • Digital marketing
No Result
View All Result
AimactGrow
No Result
View All Result

Baidu Releases Limitless OCR, a 3B Mannequin That Retains the KV Cache Flat for Lengthy-Doc Parsing

Admin by Admin
June 25, 2026
Home AI
Share on FacebookShare on Twitter


Most end-to-end OCR fashions decelerate as output grows. Every generated token provides to the KV cache. Reminiscence rises and era drags. Parsing dozens of pages turns into impractical. Baidu’s Limitless OCR addresses this immediately. It swaps the decoder’s consideration for a design that retains reminiscence fixed.

TL;DR

  • Limitless OCR is a 3B-parameter Combination-of-Specialists mannequin, with solely 500M parameters lively.
  • It replaces decoder consideration with Reference Sliding Window Consideration (R-SWA), preserving the KV cache fixed.
  • The mannequin parses dozens of pages in a single ahead move underneath a 32K most size.
  • It scores 93.23 on OmniDocBench v1.5, beating the DeepSeek OCR baseline by 6.22 factors.
  • It builds on DeepSeek OCR through continue-training, not a from-scratch run.

What’s Limitless OCR?

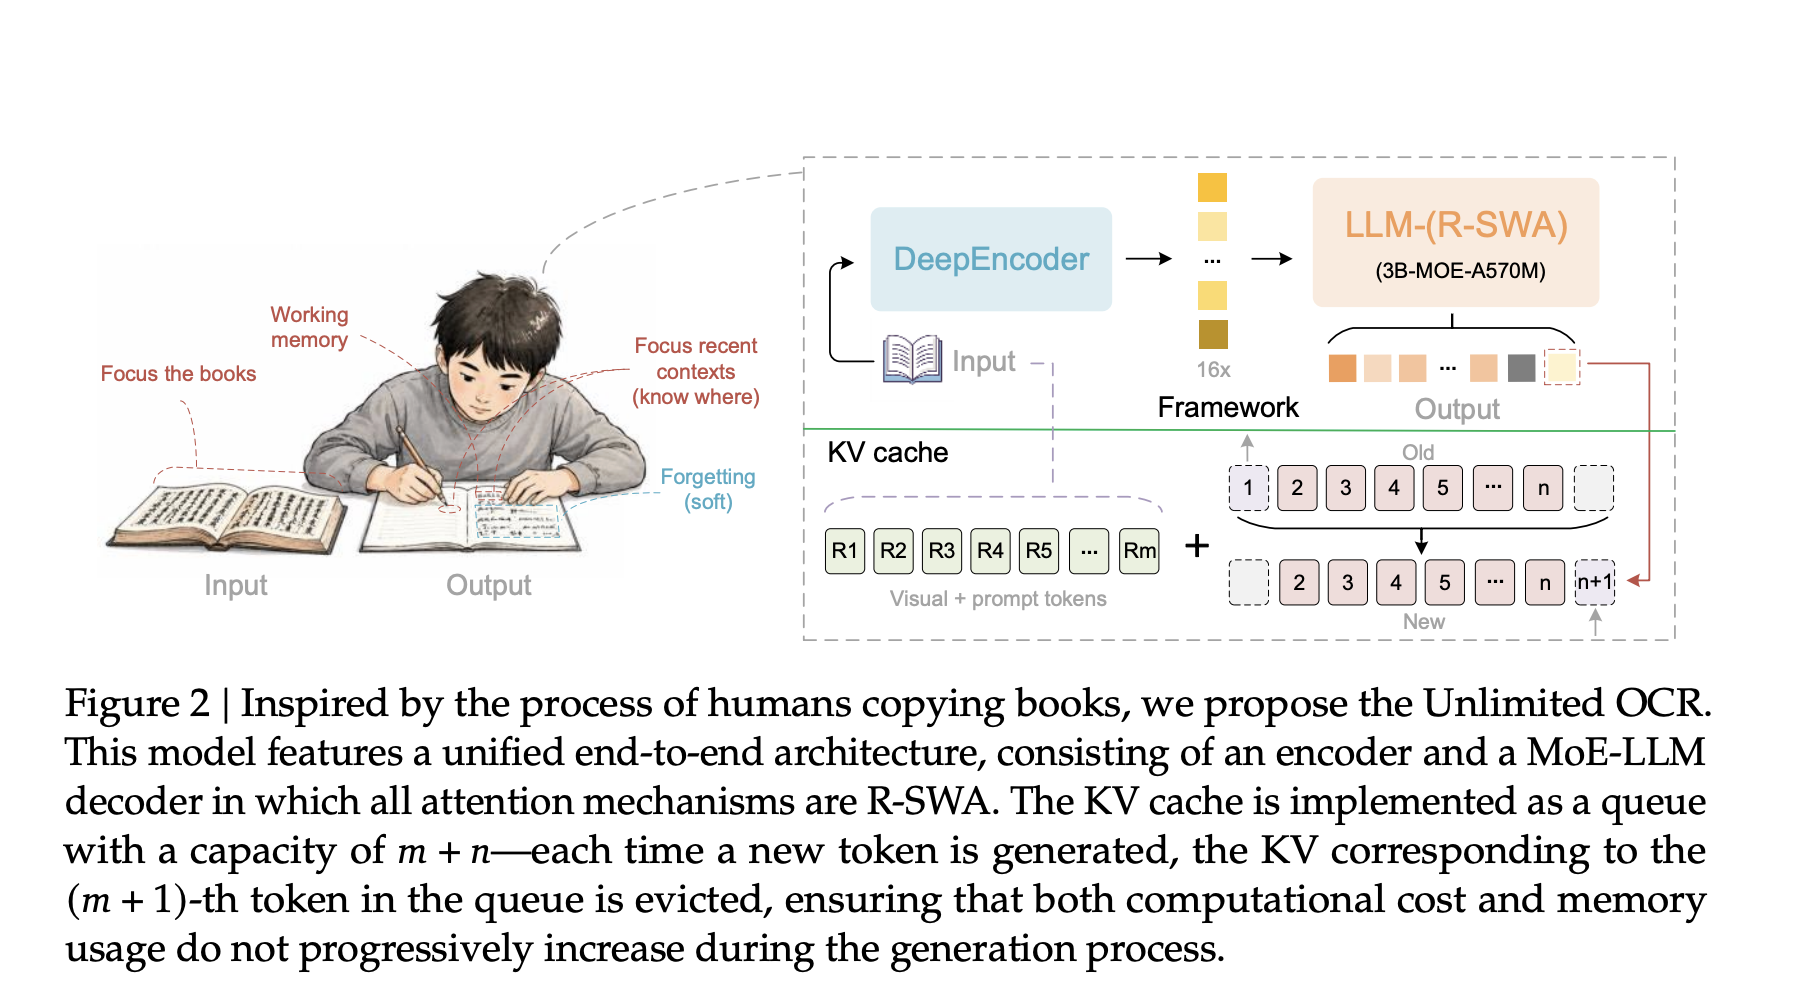
Limitless OCR takes DeepSeek OCR as its baseline. It retains the DeepEncoder and the Combination-of-Specialists decoder. The MoE design holds 3B complete parameters however prompts solely 500M at inference.

The DeepEncoder is the compression engine. It cascades a SAM-ViT underneath window consideration with a CLIP-ViT underneath world consideration. On the bridge, it applies 16× token compression. A 1024×1024 PDF picture turns into simply 256 visible tokens. Fewer enter tokens imply a smaller prefill.

DeepEncoder natively helps 5 decision modes, and Limitless OCR retains two. ‘Base’ mode runs at 1024×1024 for multi-page work. ‘Gundam’ mode makes use of dynamic decision for single pages.
https://arxiv.org/pdf/2606.23050

How R-SWA Retains the Cache Fixed

The contribution is Reference Sliding Window Consideration. Customary Multi-Head Consideration shops a key and worth for each token. As output size T grows, the cache grows with it. The scale is CMHA(T) = Lm + T. Reminiscence and latency climb with out certain.

R-SWA breaks that hyperlink. Every generated token attends to all reference tokens, which means the visible tokens and the immediate. It additionally attends to the previous n output tokens, the place n defaults to 128. All the things older is evicted. The cache turns into a set queue of dimension m + n.

The scale is CR-SWA(T) = Lm + min(n, T) ≤ Lm + n. It’s bounded by a continuing. As T grows far past n, the cache ratio traits towards zero. So reminiscence stays flat and per-step latency stays flat.

The analysis staff evaluate this to delicate forgetting. An individual copying a e-book glances on the supply and the previous few phrases. They don’t re-read every thing transcribed to date. Visible tokens by no means endure state updates. That avoids the progressive blurring seen in linear consideration. The interactive simulator under allows you to differ T and watch each caches reply.


Tags: BaiduCacheflatLongDocumentmodelOCRParsingReleasesUnlimited
Admin

Admin

Next Post
SteamOS Obtain Free – 3.8.10

SteamOS Obtain Free - 3.8.10

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Recommended.

Migrating to Swift 6 Tutorial

Migrating to Swift 6 Tutorial

June 26, 2025
Why it is best to construct relationships backward (and the way)

Why it is best to construct relationships backward (and the way)

October 1, 2025

Trending.

AI & data-driven Starbucks – Deep Brew

AI & data-driven Starbucks – Deep Brew

May 18, 2026
Attackers Exploit MCP RCE, Blind Immediate Injection and Reminiscence Credential Theft Towards AI Infrastructure

Attackers Exploit MCP RCE, Blind Immediate Injection and Reminiscence Credential Theft Towards AI Infrastructure

August 29, 2026
The Full Information to EcoGPT

The Full Information to EcoGPT

June 6, 2026
Hasbro Information Breach Uncovered Worker Private Data

Hasbro Information Breach Uncovered Worker Private Data

August 30, 2026
Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2 on a Single Workstation GPU

Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2 on a Single Workstation GPU

August 23, 2026

AimactGrow

Welcome to AimactGrow, your ultimate source for all things technology! Our mission is to provide insightful, up-to-date content on the latest advancements in technology, coding, gaming, digital marketing, SEO, cybersecurity, and artificial intelligence (AI).

Categories

  • AI
  • Coding
  • Cybersecurity
  • Digital marketing
  • Gaming
  • SEO
  • Technology

Recent News

IonQ Targets Quantum Error-Correction Bottleneck With Single-CPU DecoderIonQ Says Sin

IonQ Targets Quantum Error-Correction Bottleneck With Single-CPU DecoderIonQ Says Sin

September 23, 2026
a Semrush & Claude workflow

a Semrush & Claude workflow

September 23, 2026
  • About Us
  • Privacy Policy
  • Disclaimer
  • Contact Us

© 2025 https://blog.aimactgrow.com/ - All Rights Reserved

No Result
View All Result
  • Home
  • Technology
  • AI
  • SEO
  • Coding
  • Gaming
  • Cybersecurity
  • Digital marketing

© 2025 https://blog.aimactgrow.com/ - All Rights Reserved