Discovering new molecules for particular makes use of is a significant driver of progress in all kinds of industries, whether or not it’s pharmaceutical firms in search of new medication, or electronics or power firms in search of new supplies with specific properties. Nevertheless it’s additionally largely a trial-and-error course of, as a result of there’s not but any approach to completely predict how a given chemical compound will behave when it comes to the myriad totally different properties and responses supplies can exhibit.
Current progress has been made on utilizing synthetic intelligence and machine studying to complement or velocity up laborious calculations primarily based on bodily ideas that may no less than present some preliminary steering on which compounds could be price synthesizing and testing. Now, a brand new methodology developed at MIT exhibits that when there are few knowledge on some technologically related property, resembling ligand affinities for a lately found mobile goal for a possible drug, this method can outperform different current strategies for winnowing down the sphere of doable molecules that could be price taking a look at.
The findings had been reported within the Sept. 14 challenge of the Journal of Chemical Data and Modeling, in a paper by MIT graduate pupil Akshat Shirish Zalte and up to date graduate Jackson Burns PhD ’26, Analysis Scientist Charlles Abreu, Professor William Inexperienced, and three researchers from the chemical firm BASF.
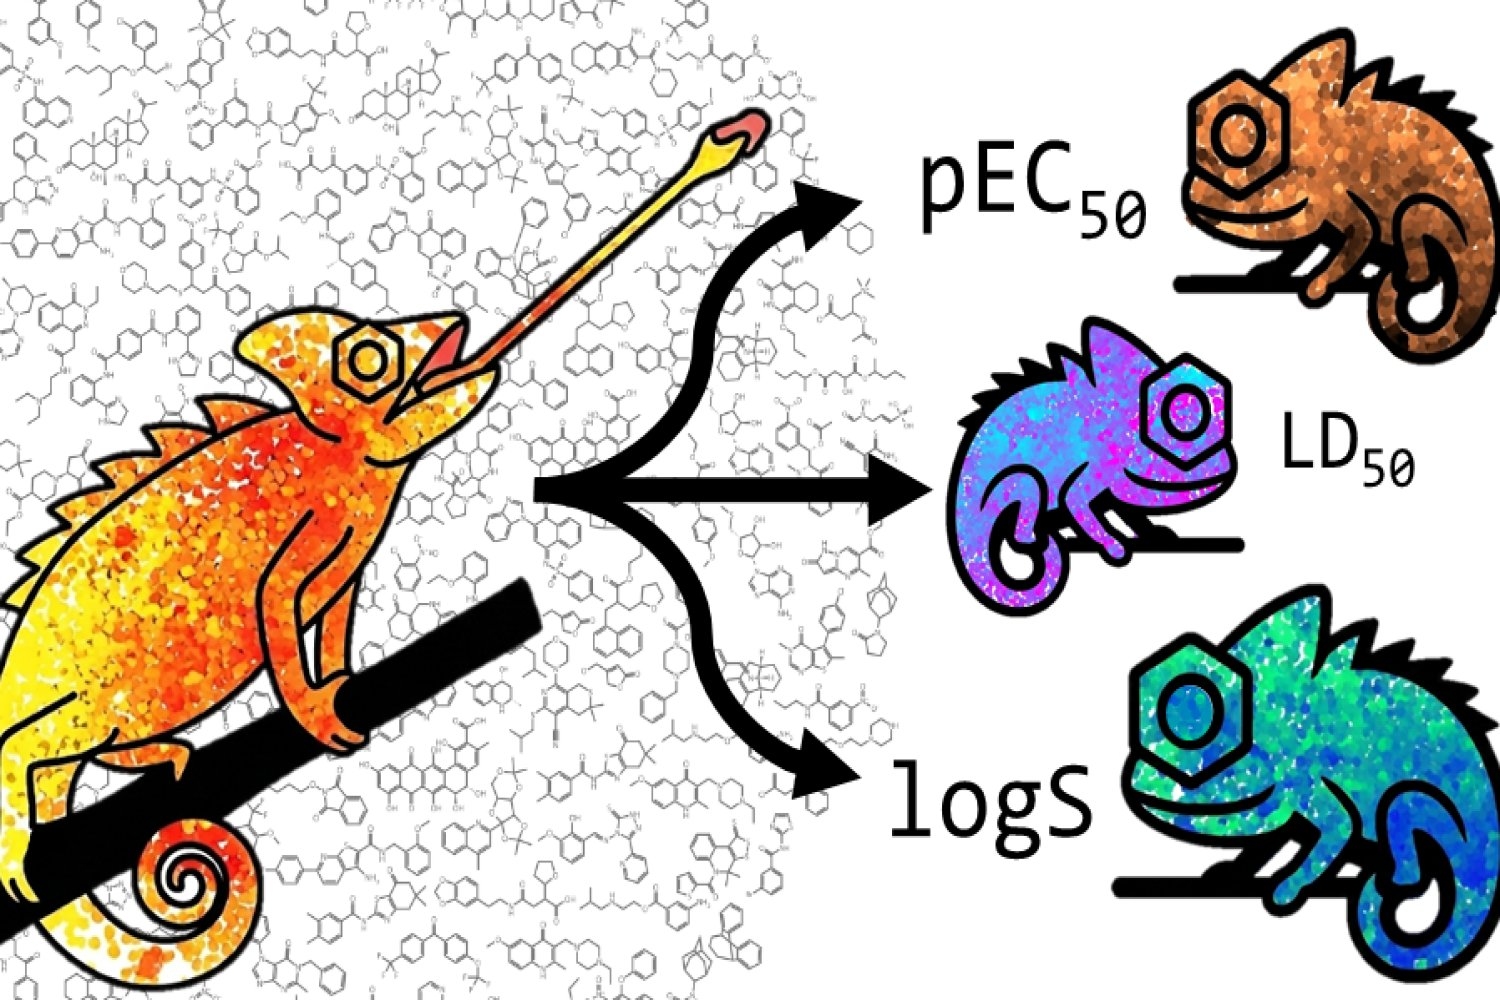
An earlier model of the paper has been on-line since final 12 months, and the open-source mannequin the group developed, known as CheMeleon, has already discovered common use by a number of pharmaceutical firms. CheMeleon was constructed utilizing ChemProp, an open-source machine-learning package deal additionally developed and maintained by the Inexperienced group at MIT, and anybody can obtain CheMeleon via ChemProp and fine-tune it for their very own functions.
Earlier this 12 months, there was a contest organized by OpenADMET for making an attempt to foretell the properties of a wide range of new molecules that had not beforehand been synthesized, says Inexperienced, who’s the Hoyt Hottel Professor of Chemical Engineering. “It was an enormous contest, lots of people participated,” he says. When the winners had been introduced, it turned out that 9 of the highest 20 entries had used CheMeleon of their course of. “So then we began getting all types of inquiries from the pharma firms about this, however our paper had simply been submitted; it wasn’t even peer-reviewed or something but.”
Whereas the paper went via that overview course of, its affect was already spreading. At the least one pharma firm, Inexperienced says, “despatched a message to all their individuals, and mentioned ‘Anytime you’re modeling a property, begin with CheMeleon, that’s our new firm coverage’” when making preliminary selections about which molecules to pursue.
The important thing to CheMeleon was pre-training a machine-learning mannequin with detailed knowledge about one million totally different molecules, in order that it will get to study correlations between the construction of a given molecule and the way it behaves with respect to a catalog of about 1,600 descriptors which were developed by chemists over many years. CheMeleon can then be fine-tuned to foretell well-known properties like solubility and viscosity, to extra esoteric properties resembling bioactivity or reactivity, with a sure protein or enzyme.
These million molecules are a minuscule fraction of the innumerable ways in which atoms can bond collectively, however they supply sufficient examples so that after the AI system has been educated on them, it may work out by itself many underlying patterns and relationships, after which apply these to a brand new, unknown molecule that’s offered to it.
“Most of as we speak’s deep-learning fashions require extra knowledge than conventional strategies,” says Zalte. Some profitable fashions use in depth knowledge from the revealed literature in chemical journals, he says. “We don’t have a look at the literature in any respect. We simply calculate a bunch of molecular descriptors like molecular weight or variety of oxygens, amongst others.” Then predicting these descriptors kinds the idea for his or her pre-training activity.
CheMeleon is a pre-trained basis mannequin. Impressed by the well-known basis fashions in language resembling ChatGPT and Claide, which basically are developed by feeding them large quantities of knowledge from the web, CheMeleon makes use of molecular descriptors of one million molecules from PubChem, a big, freely accessible database of chemical info maintained by the U.S. Nationwide Institutes of Well being.
With classical expert-driven fashions, however, specialists in a subject manually enter detailed information about their topic. In growing these classical fashions, he says, for instance, individuals know from experiments {that a} sure property of curiosity, say solubility, could relate to specific descriptors of the identical molecules, “like molecular weight, or the variety of oxygens which are current, or how branchy or cumbersome the molecule is.”
With this group’s method, they will begin with an current neural community structure and prepare it to study underlying ideas. “We’re not coaching it for a selected property, however as a normal mannequin that understands some degree of chemistry, in order that even in case you fine-tune it with just some knowledge factors for the duty you care about, you possibly can nonetheless get some good efficiency,” he says. That’s due to the truth that the mannequin is “not having to study all the things from scratch.”
To confirm its usefulness, “We in contrast our mannequin not solely towards different basis fashions which are on the market, but in addition with classical fashions leveraging expert-designed ideas,” Zalte says. Evaluating its efficiency throughout 58 take a look at circumstances, “we see that our mannequin comes out on prime.”
Inexperienced provides, “The CheMeleon basis mannequin drastically reduces the variety of molecules that must be examined experimentally to precisely predict the properties of latest molecules. This can be a large benefit, since synthesizing and testing a lot of molecules is gradual and costly.”
Apart from the MIT members, the group additionally included Jochen Sieg, Christian Feldmann, and Miriam Mathea, researchers at BASF SE in Germany. The work was supported by the Machine Studying for Pharmaceutical Discovery and Synthesis consortium, together with fellowship help from U.S. Division of Vitality and MathWorks.