After I began evaluating AI chatbots for on a regular basis work, I assumed the selection would come all the way down to who gave higher solutions. It did not. I rapidly discovered myself switching between Grok vs. Claude as a result of Grok gave me extra depth when researching fast-moving subjects, whereas Claude felt extra dependable for writing, reasoning, and dealing with lengthy paperwork. That is once I realized this wasn’t only a comparability of two AI fashions; it was a comparability of two very alternative ways of getting work completed.
To see the place every one really shines, I examined Grok and Claude throughout the duties I take advantage of AI for many: real-time analysis and information evaluation, long-form writing, complicated reasoning, doc evaluation, coding and debugging, picture understanding, and multi-turn conversations. I used the identical workflows for each instruments to maintain the comparability honest, then cross-checked my findings with G2 evaluations to see whether or not different customers reported comparable experiences.
This is what I discovered: Grok stood out for real-time analysis, significantly once I needed broader supply discovery and room to maintain exploring, whereas Claude persistently carried out higher for writing and doc evaluation. Reasoning, coding, and multi-turn conversations had been a lot nearer, with neither chatbot clearly outperforming the opposite throughout each side.
In the event you’re deciding between the 2, this hands-on Grok vs. Claude comparability breaks down how every mannequin carried out in real-world workflows so you’ll be able to select the one that most closely fits the way in which you’re employed.
Grok vs. Claude at a look
| Function | Grok | Claude |
| G2 score | 4.2/5 ⭐ | 4.6/5 ⭐ |
| Developer | xAI / SpaceXAI | Anthropic |
| Superb customers | Builders, researchers, data employees, groups utilizing linked enterprise apps, and customers monitoring stay internet/X data | Writers, builders, analysts, researchers, data employees, and groups utilizing linked enterprise apps |
| Present fashions | Grok 4.7 (flagship) | Fable 5.1, Opus 5.5, Sonnet 5.5, Haiku 5.5 |
| Greatest for | Actual-time internet/X analysis, coding, data work, linked workflows, and native picture/video creation | Writing, coding and brokers, long-document evaluation, structured data work, and linked enterprise workflows |
| Context window | 500K tokens (Grok 4.7) | As much as 1M tokens, relying on mannequin |
| Response pace | Varies with reasoning effort and workload | Varies by mannequin and reasoning effort |
| Reminiscence | Persistent context obtainable in Grok Bot; shopper reminiscence capabilities range by expertise | Reminiscence throughout conversations; as much as 5 Initiatives on Free, with expanded venture and work capabilities on paid plans |
| Actual-time knowledge entry | Native internet search and devoted X Seek for stay posts and X content material | Native internet search with citations, together with on Free |
| Picture & video technology | Native picture and video technology and modifying by means of Grok Think about | No native picture/illustration technology; can create charts, diagrams, interactive HTML/SVG visuals, designs, and different Artifacts |
| Multimodality | Textual content and picture enter; file/audio/video evaluation; native voice; picture and video technology | Textual content and picture enter; file evaluation; native Voice mode; structured visible and Artifact creation |
| Coding help | Grok 4.7 for coding, debugging, device use, and agentic workflows; Grok Bot for longer-running work | Claude Code plus Sonnet, Opus, and Fable fashions for coding, debugging, brokers, and long-running improvement work |
| Reasoning | Configurable reasoning on Grok 4.7: low, medium, excessive, xhigh | Adaptive reasoning on present Fable, Opus, and Sonnet fashions; effort varies by mannequin |
| Ecosystem and integrations | Gmail, Google Calendar/Drive, Microsoft 365 companies, Salesforce, GitHub, Notion, Linear, Field, Canva, Vercel, and customized MCP connectors | Google Workspace, Microsoft 365, Slack, GitHub, Notion, Linear, Atlassian, Canva, HubSpot, Asana, and customized distant MCP connectors |
| Privateness and knowledge management | Standalone and enterprise workspaces; connector permissions are scoped to linked accounts; xAI says supported connector knowledge comparable to Google Drive and Salesforce is not used for mannequin coaching | Shopper mannequin enchancment is opt-in with specified exceptions; business inputs/outputs aren’t used for mannequin coaching by default; connector entry inherits supply permissions |
| Pricing | Free to start out; paid SuperGrok plans enhance utilization and unlock extra capabilities | Free; Professional $17/month billed yearly ($20/month billed month-to-month); Max from $100/month (month-to-month billing solely); Crew from $20/seat/month billed yearly |
| Free plan | Sure. Free entry with decrease limits than paid SuperGrok plans | Sure. Consists of Sonnet/Haiku entry, internet search, reminiscence, voice, artifacts, file/code creation, prolonged considering, and connectors |
Word: Grok and Claude ceaselessly launch new fashions, options, and pricing adjustments. The small print above mirror data obtainable as of October 2026 and should change over time.
Grok vs. Claude: What’s totally different and what’s not?
Grok and Claude can each write, code, summarize paperwork, analyze information, and reply complicated questions, so it is simple to imagine they’re interchangeable. As I in contrast them throughout totally different workflows, I discovered that, like many trendy LLMs, they share comparable capabilities however remedy issues in very alternative ways. These variations develop into a lot simpler to identify as soon as you progress past function lists and begin evaluating how every chatbot suits the work you truly do.
Grok vs. Claude: What’s totally different?
Though Grok and Claude overlap in lots of areas, the next variations have the largest affect on how every chatbot suits into real-world workflows.
- Actual-time entry to X knowledge (Grok’s greatest aggressive benefit): Grok’s direct connection to X adjustments the way in which it approaches analysis. Along with internet search, it has a devoted X Seek for stay posts, customers, threads, and different social content material. Claude additionally helps real-time internet search with citations, however it would not have an equal native X search layer. In case your work will depend on monitoring trade conversations, monitoring public sentiment, or following discussions as they evolve, Grok affords a definite benefit.
- Visible creation (Grok generates media; Claude builds structured visuals): Grok natively generates photos and movies through Grok Think about, making it well-suited to workflows involving unique visible media. Claude takes a unique method: it will possibly analyze photos and likewise create charts, diagrams, interactive visuals, designs, shows, and different Artifacts. The excellence is not merely “creates vs. analyzes,” however native media technology vs. structured visible creation.
- Voice interactions (Each assist voice, however Grok goes additional with digicam enter): Grok affords native voice conversations with stay camera-based interactions, so it will possibly reply to what you present it in actual time. Claude additionally helps full Voice mode, letting customers swap naturally between talking and typing, use internet search, and entry linked instruments throughout a voice dialog.
- Security philosophy (Claude is constitution-led; Grok is extra overtly positioned): Claude is explicitly formed by Anthropic’s Structure, which guides its values, conduct, and security boundaries. xAI has traditionally positioned Grok as extra prepared to have interaction broadly and with a much less typical tone. My intent right here is to not suggest that one is universally extra restrictive or permissive, since each merchandise proceed to evolve.
- Workflow integrations (Each now join broadly throughout enterprise apps): Claude helps a variety of internet and customized MCP connectors throughout instruments like Slack, Google Drive, GitHub, Notion, Linear, and extra, with some connectors providing interactive in-chat experiences. Grok has additionally expanded considerably, with connectors for companies comparable to Field, Canva, GitHub, Linear, Notion, Vercel, Salesforce, and customized MCP servers. At this level, the distinction is much less about connector breadth and extra about how every assistant suits into your present workflow.
Grok vs. Claude: What’s comparable?
Regardless that they take totally different approaches, Grok and Claude share most of the capabilities folks now anticipate from a contemporary AI assistant. Whether or not you are creating content material, researching a subject, or fixing technical issues, each platforms present a strong basis earlier than their particular person strengths start to face out.
- On a regular basis AI help (Constructed for contemporary data work): Writing emails, summarizing reviews, brainstorming concepts, explaining technical ideas, reviewing code, and answering common questions are all duties that each chatbots deal with confidently. It is one of many causes they proceed to rank among the many AI chatbots price utilizing for on a regular basis productiveness.
- Persistent conversations (Designed for ongoing initiatives): Neither chatbot limits you to one-off interactions. Each assist longer conversations by means of reminiscence and project-based capabilities, making it simpler to revisit earlier discussions, construct on earlier responses, and maintain complicated work transferring with out always repeating context.
- Massive doc understanding (Made for long-form content material): Whether or not I am working with prolonged analysis papers, technical documentation, contracts, or intensive codebases, each platforms are constructed to course of substantial quantities of data in a single dialog. That makes them way more sensible for knowledge-intensive work than earlier generations of AI assistants.
- Multimodal understanding (Extra than simply textual content prompts): Pictures, screenshots, PDFs, spreadsheets, and different uploaded information develop into a part of the dialog on each platforms. As a substitute of merely describing visible content material, every chatbot can purpose about what it sees and mix that data with text-based directions to provide extra related responses.
- Versatile entry level (Straightforward to attempt earlier than committing): Each platforms provide free entry alongside premium subscriptions, permitting customers to discover their capabilities earlier than paying for increased utilization limits or superior options. That additionally makes it simpler to check them towards a number of the hottest AI instruments proper now earlier than deciding which assistant most closely fits your workflow.
Options and product pages can solely let you know a lot. To know how Grok and Claude truly carry out, I put each chatbots by means of a collection of real-world duties that mirror how folks use AI every single day.
How I in contrast Grok vs. Claude: My prompts and analysis standards
To maintain the comparability as honest as potential, I examined Grok and Claude utilizing the identical prompts, workflows, and success standards throughout a collection of real-world duties. I used their free plans, averted any customized directions or model-specific optimizations, and evaluated every chatbot based mostly on the way it dealt with on a regular basis work reasonably than benchmark scores.
I examined each chatbots throughout the next workflows:
- Actual-time analysis: Summarizing latest AI information, distinguishing confirmed data from hypothesis, and figuring out rising tendencies.
- Lengthy-form writing: Drafting a weblog introduction whereas following tone, viewers, and elegance constraints.
- Reasoning and decision-making: Fixing a sensible B2B SaaS advertising and marketing situation with a number of enterprise constraints.
- Doc evaluation: Reviewing a 425-page analysis report, extracting key findings, flagging claims for verification, and summarizing insights.
- Coding and debugging: Discovering bugs, explaining points, correcting JavaScript code, and dealing with further edge circumstances.
- Picture understanding: Deciphering a benchmark chart and answering questions based mostly solely on the visible data supplied.
- Multi-turn conversations: Rewriting content material for a unique viewers whereas preserving context and following new directions.
I evaluated each response utilizing the identical standards:
- Accuracy: Did the chatbot reply the immediate appropriately with out making unsupported assumptions?
- Instruction following: Did it fulfill each requirement, together with formatting, tone, and constraints?
- Reasoning and usefulness: Have been the reasons logical, actionable, and acceptable for the duty?
- Output high quality: Was the response properly organized, simple to make use of, and prepared with minimal modifying?
To enrich my hands-on testing, I additionally reviewed G2 product knowledge and consumer suggestions to evaluate whether or not my expertise aligned with verified customers’ reviews.
Disclaimer: AI responses can range based mostly on mannequin updates, session historical past, and immediate wording. I carried out these hands-on assessments in October 2026; the outcomes mirror the fashions and options obtainable at the moment.
Grok vs. Claude: How they really carried out in my assessments
To see how Grok and Claude evaluate past function lists, I examined them throughout a variety of real-world duties, from researching present occasions and writing long-form content material to fixing complicated issues, analyzing paperwork, and producing code. For every take a look at, here is how I will break it down:
- What stood out? I will spotlight the largest variations I observed in how every chatbot approached the duty, together with response high quality, reasoning, accuracy, and any surprising nuances.
- Who did it higher? I will let you know which chatbot delivered the extra helpful general expertise, based mostly on the standard of its output, the quantity of refinement it required, and the way successfully it accomplished the duty.
- Remaining verdict: My sincere tackle which chatbot I might select for that particular use case and why.
Let’s get into it!
1. Actual-time analysis and information evaluation: Grok researches deeper, Claude curates higher
One of many first issues I needed to guage was how properly Grok and Claude dealt with a time-sensitive analysis job. I requested each chatbots to summarize the 5 greatest AI information tales from the previous 30 days, distinguish confirmed developments from hypothesis, and determine the tendencies enterprise professionals ought to control. I used the very same immediate on each instruments.
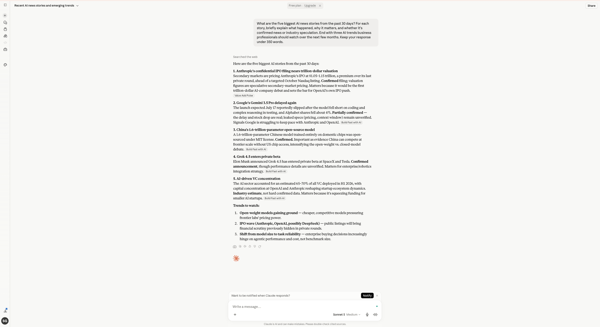
Claude’s response to the real-time analysis immediate
Claude mechanically searched the net earlier than responding, even on the free plan. It returned 5 well-structured AI information tales, clearly labeling every one as Confirmed, Partially confirmed, or an Business estimate, whereas supporting the summaries with inline supply citations. I additionally appreciated that each story briefly defined why it mattered as a substitute of merely reporting the information. Somewhat than making an attempt to cowl each latest improvement, Claude centered on producing a concise, editor-like briefing that was simple to scan and perceive.
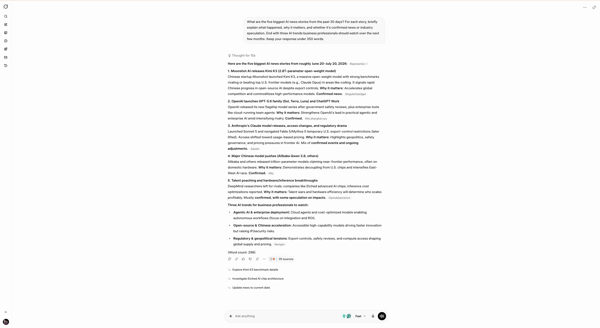
Grok’s response to the real-time analysis immediate
Grok took a extra research-oriented method. After spending 15 seconds reasoning by means of the immediate, it returned 5 tales backed by 35 sources and lined a broader mixture of AI developments, from frontier fashions and open-source AI to {hardware}, regulation, and enterprise adoption. What stood out most was that each story paired the information with a devoted “Why it issues” rationalization, serving to join particular person updates to broader trade tendencies. It additionally surfaced follow-up analysis options after finishing the abstract, making the response really feel much less like a completed briefing and extra like a place to begin for deeper analysis. For anybody making an attempt to maintain up with developments in rising AI software program, that further breadth and discoverability added significant worth.
Each chatbots dealt with the duty properly, however they approached it in a different way. Claude delivered a concise, editor-like briefing, whereas Grok surfaced a broader vary of AI developments backed by considerably extra sources and follow-up analysis paths. Since this take a look at centered on supporting real-time analysis reasonably than merely summarizing latest occasions, Grok finally supplied the extra helpful analysis expertise.
Winner: Grok
2. Lengthy-form writing and modifying: Claude sounds extra human, Grok stays on message
One of the crucial widespread causes folks use AI chatbots is to draft content material, so I needed to see how every dealt with a sensible writing task. I requested each Grok and Claude to jot down a 200-word introduction for a weblog put up titled “Why AI Brokers Are the Subsequent Massive Shift for Enterprise Groups.” The immediate additionally requested for knowledgeable but conversational tone, to keep away from widespread AI buzzwords comparable to “revolutionary” and “game-changing,” and to finish with a hook that may encourage readers to maintain studying.
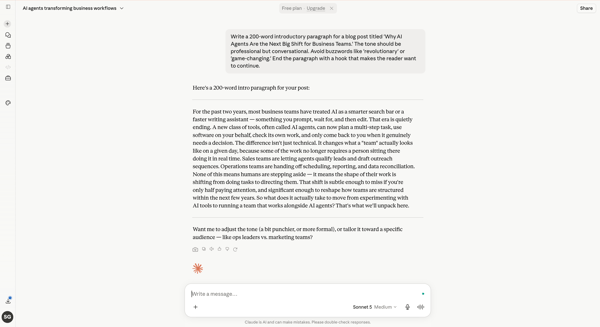
Claude’s response to the writing immediate
Claude took a noticeably totally different method from the very first sentence. As a substitute of counting on a well-known AI opener, it reframed how companies have historically used AI earlier than introducing the shift towards AI brokers, giving the introduction a clearer narrative development. The writing remained conversational with out turning into overly informal, averted the buzzwords I explicitly requested it to omit, and naturally constructed towards the closing hook.
The opening paragraph instantly establishes why AI brokers matter to enterprise groups earlier than transitioning into the primary matter. It already learn like one thing I might anticipate from one of many higher AI writing turbines. If I had been modifying it for publication, I might primarily tighten just a few sentences for brevity and regulate the phrasing to raised match G2’s editorial type, however I would not really feel the necessity to rewrite the introduction itself.
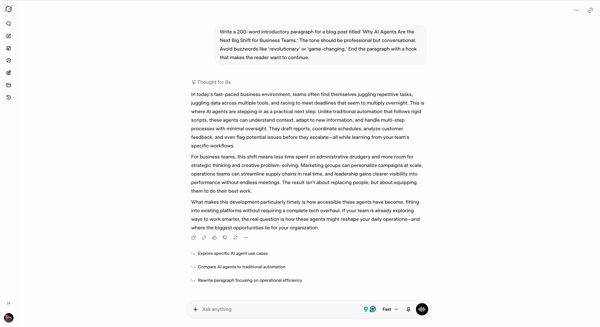
Grok’s response to the writing immediate
Grok produced a well-structured introduction that stayed on matter and lined the important thing concepts I used to be on the lookout for. It defined AI brokers by means of sensible enterprise examples and maintained a logical move from starting to finish. Nevertheless, the opening instantly stood out to me: “In in the present day’s fast-paced enterprise surroundings…”
As somebody who writes professionally, that is one of the vital recognizable AI-generated openings, and it made the introduction really feel predictable earlier than I even reached the second sentence. The remainder of the response remained informative, however I might nonetheless wish to rewrite the opening to provide it a extra distinctive opening.
Each chatbots adopted the immediate and produced well-structured introductions. Grok centered on speaking the important thing concepts clearly, whereas Claude paired that readability with a extra unique opening and a extra pure narrative move. That made Claude’s introduction really feel nearer to one thing I might publish with solely mild modifying.
Winner: Claude
3. Advanced reasoning and decision-making: Claude constructions higher, Grok thinks extra virtually
I needed to see how properly Grok and Claude dealt with a enterprise resolution with no easy reply. Somewhat than asking a logic puzzle, I gave each chatbots a sensible B2B SaaS advertising and marketing situation with a number of price range allocation choices, enterprise constraints, and one clear goal: advocate the choice most probably to maximise pipeline affect earlier than the top of Q3 whereas explaining the reasoning behind the choice. I wasn’t on the lookout for the “proper” reply as a lot as I needed to know how every chatbot evaluated trade-offs earlier than making a advice.
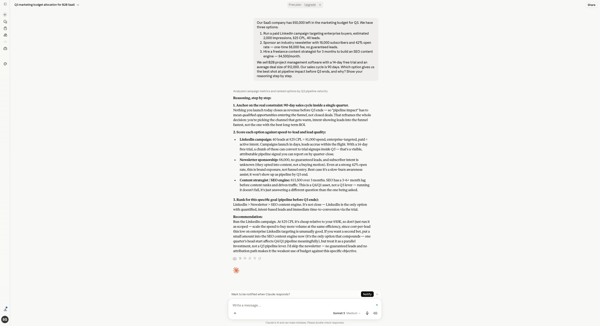
Claude’s response to the reasoning immediate
Claude approached the issue methodically, first defining what “pipeline affect earlier than Q3 ends” meant earlier than evaluating every choice towards the identical standards. It walked by means of the strengths and limitations of each advice, defined why LinkedIn greatest matched the target, and saved the reasoning tightly organized from begin to end. I additionally appreciated that it acknowledged the place the opposite choices nonetheless made sense reasonably than dismissing them outright, making the ultimate advice really feel balanced and well-supported.
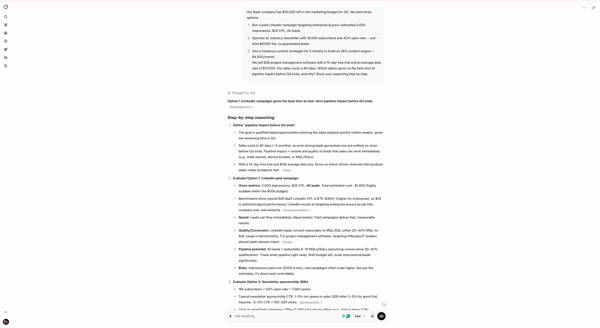
Grok’s response to the reasoning immediate (half 1)
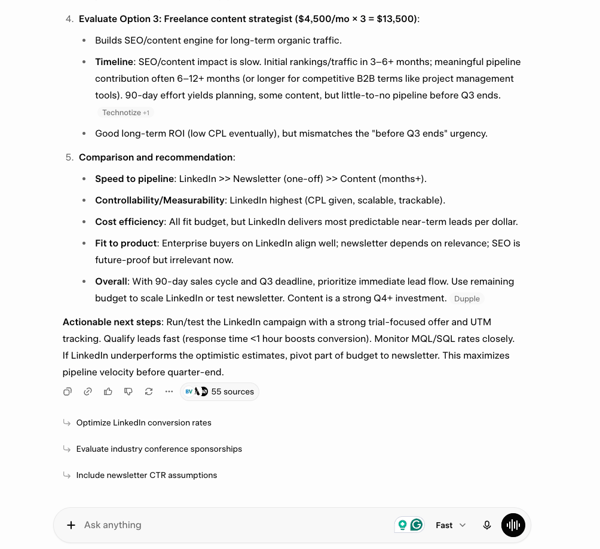
Grok’s response to the reasoning immediate (half 2)
Grok reached the identical advice however took a extra execution-oriented method. Past evaluating the three choices, it estimated potential outcomes, highlighted sensible dangers, and completed with actionable subsequent steps for implementing the advice. I additionally appreciated the follow-up options for optimizing marketing campaign efficiency, which made the response really feel much less like a one-time reply and extra like a sensible decision-making information.
Each chatbots dealt with the situation thoughtfully with out overlooking the enterprise constraints within the immediate. Claude made it simpler to know why the advice was one of the best match, whereas Grok centered extra on find out how to execute it as soon as the choice had been made.
Winner: Cut up (Claude supplied a extra structured reasoning framework, whereas Grok matched it with actionable suggestions and detailed decision-making steering.)
4. Massive doc evaluation: Claude follows directions higher, Grok provides strategic context
One of the crucial sensible makes use of for an AI chatbot is making sense of lengthy reviews with out having to learn lots of of pages your self. To check this, I uploaded the 425-page Stanford HAI AI Index Report 2026 and requested each Grok and Claude to determine the three most vital findings for a B2B SaaS founder, flag claims that deserved further verification, and summarize the report’s place on AI adoption in enterprise software program.
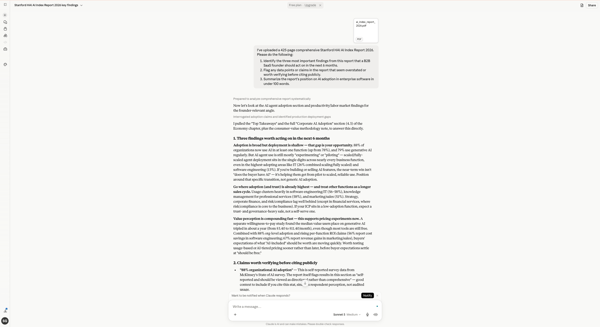
Claude’s response to the doc evaluation immediate (half 1)
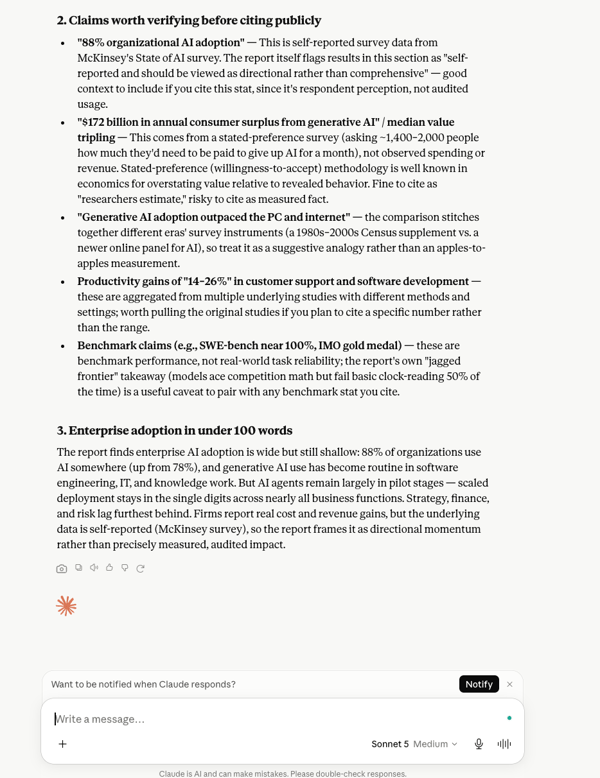
Claude’s response to the doc evaluation immediate (half 2)
Claude adopted the construction of my immediate carefully, separating its response into the three requested sections. It recognized the important thing findings, defined why sure statistics warranted further verification, and summarized the report’s place on enterprise AI adoption inside the requested phrase restrict.
I significantly appreciated the way it defined the methodology behind a number of claims, making the findings simpler to cross-check towards the unique report. The response stayed centered on the supply materials and introduced the knowledge clearly with out including pointless interpretation.
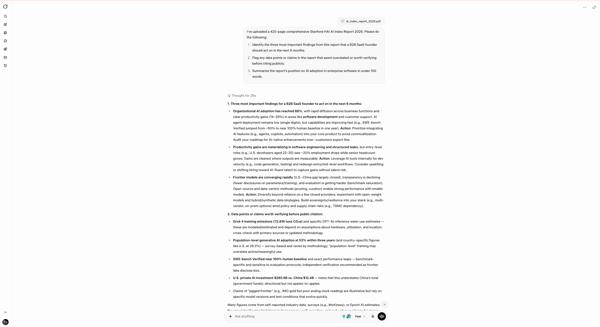
Grok’s response to the doc evaluation immediate (half 1)
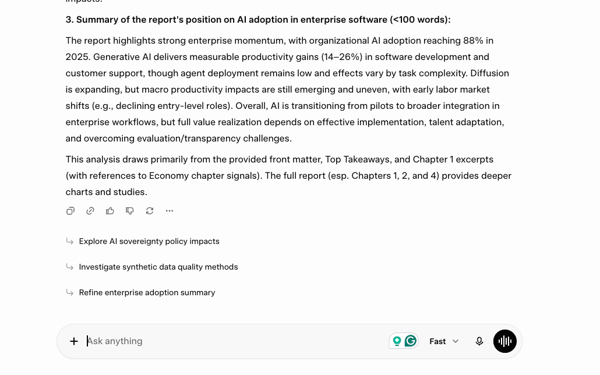
Grok’s response to the doc evaluation immediate (half 2)
Grok additionally accomplished all three elements of the immediate, figuring out key findings, flagging statistics requiring verification, and summarizing enterprise AI adoption. What stood out was the way it translated the analysis into sensible suggestions by means of devoted Motion callouts, connecting the findings to broader enterprise choices.
I additionally appreciated that Grok defined why sure statistics deserved further scrutiny reasonably than merely itemizing them. Its response mixed doc evaluation with actionable insights, making it helpful for readers seeking to perceive the findings and think about their enterprise implications.
Each chatbots efficiently accomplished the doc evaluation job, however their approaches differed. Claude emphasised structured, source-focused reporting, whereas Grok linked the findings to sensible enterprise choices. Neither confirmed a transparent shortcoming in finishing the requested work, making this a good cut up.
Winner: Cut up (Claude delivered a structured, source-focused evaluation, whereas Grok complemented its findings with actionable enterprise suggestions.)
5. Coding and debugging: Claude explains higher, Grok validates additional
Writing code is one factor, however debugging present code often tells me far more about an AI assistant’s reasoning. For this take a look at, I gave each Grok and Claude a damaged JavaScript perform and requested them to determine the bugs, clarify what was improper, and supply a corrected model that additionally dealt with further edge circumstances.
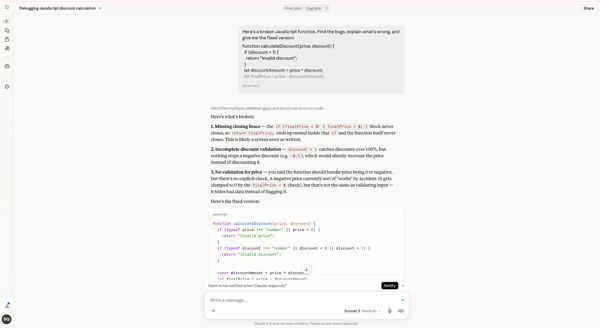
Claude’s response to the coding and debugging immediate (half 1)
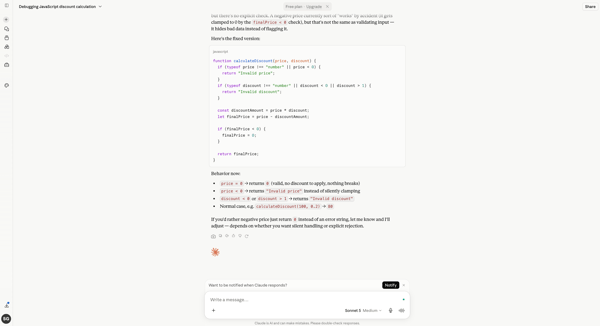
Claude’s response to the coding and debugging immediate (half 2)
Claude instantly centered on explaining why the code failed earlier than presenting an answer. It recognized the lacking closing brace, highlighted gaps within the validation logic, and defined why silently accepting damaging costs might result in incorrect conduct. I additionally appreciated that it walked by means of how the revised perform would behave underneath totally different inputs, making the fixes simple to know with out having to learn each line of code.
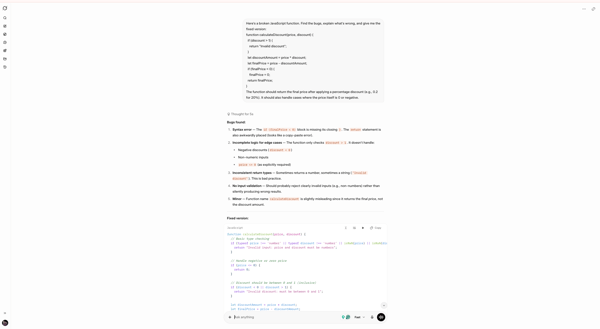
Grok’s response to the coding immediate (half 1)
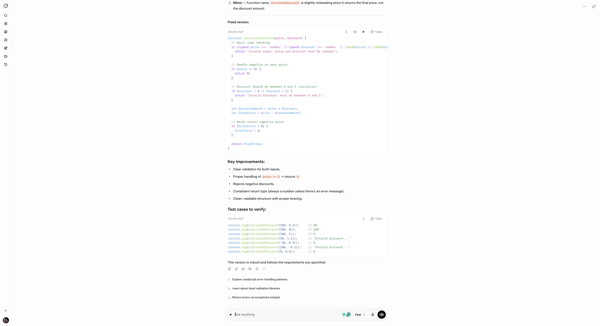
Grok’s response to the coding immediate (half 2)
Grok recognized the identical core points however leaned extra towards strengthening the implementation. Alongside the corrected perform, it expanded validation to cowl further edge circumstances, summarized the important thing enhancements, and included ready-to-run take a look at circumstances to make it simple to confirm the answer. I additionally appreciated smaller options, comparable to renaming the perform to raised mirror its goal, which confirmed consideration to extra than simply fixing the rapid bugs.
Each chatbots demonstrated why they’re amongst in the present day’s strongest AI coding assistants. Claude made the debugging course of simpler to know by means of clear explanations, whereas Grok centered on making the ultimate answer extra strong and simpler to validate. Which method is extra priceless finally will depend on whether or not you prioritize understanding the repair or verifying it in observe.
Winner: Cut up (Claude defined the reasoning behind every repair extra clearly, whereas Grok strengthened the implementation with further validation and sensible testing.)
6. Picture understanding and visible evaluation: Grok stays nearer to the chart, Claude provides broader context
Understanding photos is not nearly recognizing objects anymore. I needed to see how properly Grok and Claude might interpret a fancy benchmark chart, extract significant insights, and clarify what the visualization truly confirmed reasonably than counting on common AI data. I requested each chatbots to reply three questions in regards to the chart whereas retaining the response underneath 150 phrases.
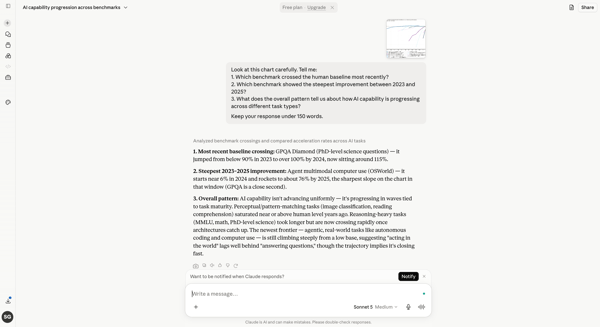
Claude’s response to the picture evaluation immediate
Claude took a extra interpretive method to the chart as a substitute of merely describing what it confirmed. Somewhat than itemizing particular person observations, it grouped associated findings collectively and defined the broader story behind the outcomes. I appreciated that it went past surface-level observations and tried to elucidate what the findings meant reasonably than merely repeating what was already seen.
At occasions, although, it appeared to attract on its broader understanding of AI benchmarks so as to add context past the knowledge immediately introduced within the chart. Whereas that made the reason richer, it additionally meant some conclusions felt much less tightly tied to the visualization itself.
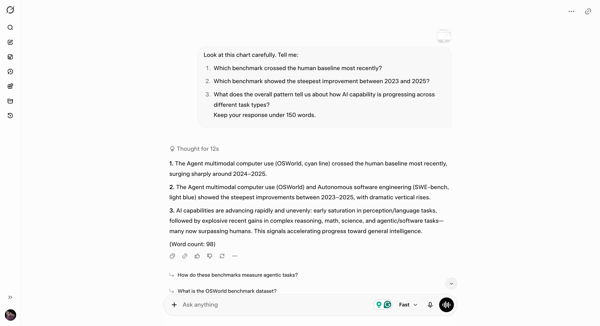
Grok’s response to the picture evaluation immediate
Grok answered every of the three questions immediately and stayed carefully aligned with the knowledge introduced within the chart. Somewhat than increasing into broader interpretations, it centered on figuring out the requested benchmarks and summarizing the general development in a concise, well-structured response. I additionally appreciated that it stayed inside the requested phrase restrict whereas retaining the reason clear and simple to validate towards the visualization.
Each chatbots demonstrated they’re able to understanding complicated visible inputs, a functionality more and more vital past conventional AI picture turbines. Claude added helpful context round what the tendencies might imply, whereas Grok remained extra carefully grounded within the chart itself. Since this take a look at evaluated how precisely every chatbot interpreted the visible reasonably than how a lot further context it might present, I discovered Grok’s response extra carefully aligned with the duty.
Winner: Grok
7. Multi-turn conversations and instruction following: Claude adapts higher, Grok preserves context naturally
One of many best methods to check an AI chatbot’s conversational reminiscence is by introducing new directions with out repeating the unique context. For this take a look at, I first requested each Grok and Claude to jot down a product description for AI-powered expense-tracking software program geared toward startup founders. I then adopted up by asking them to rewrite it for enterprise finance groups, maintain it underneath 40 phrases, and add a line about safety and compliance.
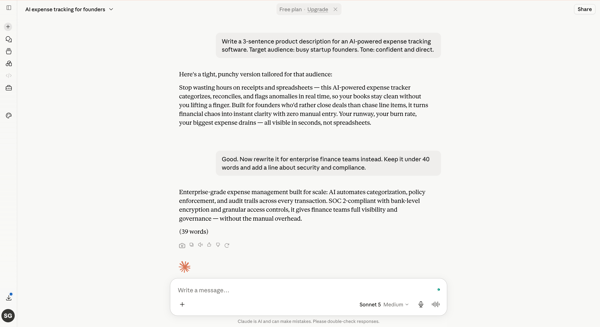
Claude’s response to the follow-up immediate
Claude dealt with the transition with no need clarification. It understood that I needed the present copy rewritten reasonably than changed, shifted the messaging towards enterprise finance groups, and naturally included safety, compliance, and governance into the brand new model. I additionally appreciated that it displayed the ultimate phrase rely, making it simple to substantiate it had stayed inside the requested restrict. Extra importantly, the rewrite felt intentional. It wasn’t merely shortening the unique copy; it revised the messaging for a unique viewers whereas preserving the core product worth.
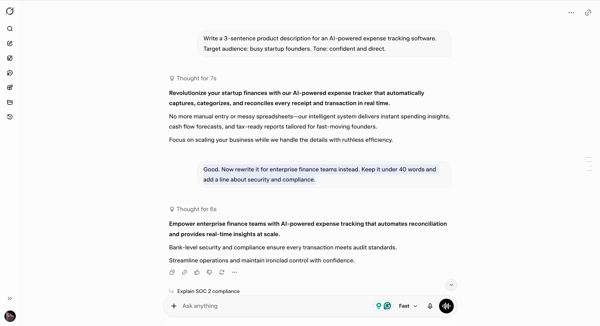
Grok’s response to the follow-up immediate
Grok additionally carried the dialog ahead with out dropping context. It remembered the unique product, shifted the messaging towards enterprise finance groups, and efficiently included the requested safety and compliance language. The rewrite remained concise, preserved the unique immediate’s assured tone, and responded to the brand new directions with out requiring any clarification. The interplay felt easy and constant from one immediate to the subsequent.
Each chatbots dealt with the follow-up directions properly, displaying they’ll handle multi-step conversations with out dropping context. Claude produced the extra audience-aware rewrite, whereas Grok excelled at sustaining conversational continuity and adapting naturally because the directions developed.
Winner: Cut up (Claude delivered extra audience-specific wording, whereas Grok preserved conversational context and instruction continuity with out dropping the unique context.)
Grok vs. Claude: My analysis scorecard
This is a fast take a look at how every chatbot carried out throughout all seven hands-on assessments.
| Job | Winner | Why it gained |
| Actual-time analysis and information evaluation | Grok 🏆 | Surfaced a broader vary of developments, backed them with considerably extra sources, and made deeper follow-up analysis simpler. |
| Lengthy-form writing and modifying | Claude 🏆 | Delivered a extra unique opening, smoother narrative move, and a draft that felt nearer to publication-ready. |
| Advanced reasoning and decision-making | Cut up | Claude made the choice logic simpler to comply with, whereas Grok added extra actionable implementation steering. |
| Massive doc evaluation (PDFs and reviews) | Cut up | Claude organized and defined the findings clearly, whereas Grok linked the evaluation to sensible enterprise actions. |
| Coding and debugging | Cut up | Claude made the fixes simpler to know, whereas Grok strengthened the implementation with broader validation and ready-to-run assessments. |
| Picture understanding and visible evaluation | Grok 🏆 | Stayed extra carefully aligned with the chart itself, making the response simpler to validate towards the visible proof. |
| Multi-turn conversations and instruction following | Cut up | Claude tailored the rewrite extra successfully for the brand new viewers, whereas Grok preserved conversational continuity because the directions developed. |
Key insights on Grok vs. Claude from G2 Knowledge
I additionally checked out G2 evaluation knowledge to know how Grok and Claude evaluate in consumer satisfaction, adoption, and have efficiency. This is what stood out:
Satisfaction rankings
- Claude scores extremely for ease of admin (92%), ease of doing enterprise with (92%), and ease of use (91%), suggesting customers worth its general usability regardless of its broader enterprise focus.
- Grok performs properly for response technology pace (96%), ease of use (94%), and meets necessities (94%), reflecting the quick, responsive expertise I observed all through my hands-on testing.
Prime industries represented
- Claude is most generally used throughout data expertise and companies, pc software program, advertising and marketing and promoting, consulting, and hospital and well being care, highlighting its sturdy adoption amongst data employees and enterprise groups.
- Grok is most strongly represented in structure and planning, increased training, monetary companies, logistics and provide chain, and pc software program, displaying adoption throughout a various mixture of industries.
Highest-rated options
- Claude scores highest in textual content technology (94%), area adaptability (89%), and adherence to moral tips (86%), reinforcing its strengths in long-form writing, structured reasoning, and enterprise-focused use circumstances.
- Grok stands out for textual content technology (100%), response technology pace (96%), and ease of integration (93%), making it significantly well-suited for quick analysis workflows and day-to-day interactions.
Lowest-rated options
- Claude scores lowest for effectivity in multi-turn conversations (76%), API user-friendliness (81%), and bias mitigation (82%), suggesting that longer conversational workflows and developer expertise nonetheless have room for enchancment.
- Grok receives its lowest scores for contextual understanding (79%), high quality of responses (81%), and customization flexibility (89%), indicating that customers worth its pace however nonetheless anticipate extra consistency and deeper contextual reasoning.
Taking a look at extra AI chatbot matchups?
In the event you’re evaluating a number of AI assistants earlier than making your resolution, these detailed comparisons may help you perceive the place every one stands:
Who ought to use Grok vs. Claude?
| Consumer position/want | Advisable device | Why |
| Researchers monitoring breaking information and trade tendencies | Grok | Reside internet search, broader supply protection, and follow-up analysis options make it higher for fast-moving subjects. |
| Content material entrepreneurs, writers, and editors | Claude | Produces extra pure, audience-aware writing that wants much less modifying earlier than publishing. |
| Enterprise professionals reviewing prolonged reviews and PDFs | Claude | Follows detailed directions carefully and organizes complicated data into structured, actionable summaries. |
| Determination-makers evaluating complicated enterprise situations | Claude | Breaks down trade-offs methodically and presents structured reasoning that is simpler to guage. |
| Builders debugging and enhancing code | Grok | Provides broader validation, sensible take a look at circumstances, and implementation options past fixing the rapid challenge. |
| Customers counting on AI for ongoing conversations and iterative work | Grok | Maintains conversational context naturally whereas adapting to new directions throughout a number of prompts. |
| Professionals who want one AI assistant for on a regular basis data work | Claude | Delivers probably the most constant expertise throughout writing, reasoning, doc evaluation, and instruction-heavy duties. |
| Customers who prioritize pace and present data | Grok | Excels at real-time analysis, recent data retrieval, and exploring quickly evolving subjects. |
Regularly requested questions (FAQs) on Grok vs. Claude
Acquired extra questions? G2 has the solutions!
Q1. What’s the distinction between Grok and Claude?
The most important distinction is their focus. Grok excels at real-time analysis, stay internet data, and quick exploration, whereas Claude performs higher for long-form writing, structured reasoning, and doc evaluation. The only option will depend on how you propose to make use of AI every single day.
Q2. Is Grok or Claude higher for reasoning, evaluation, and writing?
Neither chatbot led throughout all three. Claude wrote a extra participating introduction and arranged doc findings clearly; Grok contributed sensible reasoning steps and supply discovery. Each accomplished my decision-making take a look at, leading to a cut up.
Q3. Can Grok and Claude analyze photos and paperwork?
Sure. Each can interpret uploaded photos and analyze lengthy paperwork. In my assessments, Grok saved its chart evaluation carefully tied to the visible, whereas Claude organized doc findings clearly. Each accomplished the requested evaluation duties.
This autumn. When ought to I select Grok over Claude?
Select Grok whenever you want up-to-date data, broader internet analysis, and quicker exploration of evolving subjects. Its real-time analysis capabilities, intensive supply protection, and follow-up options make it significantly helpful for monitoring information, tendencies, and trade developments.
Q5. When ought to I select Claude over Grok?
Select Claude when your work entails long-form writing, doc evaluation, structured reasoning, or refining complicated concepts. It persistently adopted directions extra carefully and produced polished, audience-aware responses that required much less modifying throughout my hands-on testing.
Q6. Which AI chatbot follows complicated directions higher?
Claude adopted complicated directions extra persistently throughout my analysis. It adhered carefully to formatting, viewers, and content material necessities throughout writing, reasoning, and doc evaluation duties, whereas Grok sometimes expanded past the immediate with further suggestions and context.
Q7. Does Grok have a bonus over Claude for real-time data?
Sure, particularly for stay X posts and social conversations. Grok has devoted X search, whereas each chatbots can entry present internet data. In my analysis take a look at, Grok additionally surfaced extra sources and follow-up paths.
Q8. Can Grok and Claude bear in mind earlier conversations?
Sure, however their reminiscence options differ. Claude affords reminiscence throughout conversations, together with on Free, whereas Grok Bot helps persistent context for ongoing work. Each additionally retained context inside my multi-turn writing take a look at.
Q9. Is something higher than Claude?
Some AI assistants could go well with explicit duties higher than Claude. In my assessments, Grok was extra helpful for exploring stay X-related data and chart-specific solutions, whereas Claude delivered a extra participating writing pattern.
Q10. Which AI is healthier than Grok?
That will depend on the duty. Claude delivered a extra participating introduction in my writing take a look at, whereas Grok was helpful for stay analysis and chart evaluation. Neither chatbot persistently outperformed the opposite throughout all seven assessments.
Q11. Is Grok probably the most highly effective AI?
There is no such thing as a single, common measure of AI energy. Grok affords native X search and picture/video technology, however one of the best assistant will depend on accuracy, job completion, workflow match, and the fashions being in contrast.
Q12. Why is Claude controversial?
Debate round Claude typically facilities on AI security guidelines, refusals, privateness, and the reliability of generated solutions. Anthropic publishes its method to security, however customers ought to nonetheless confirm vital outputs and evaluation present knowledge insurance policies.
Grok vs. Claude: My ultimate verdict
After testing Grok and Claude throughout real-world workflows, I do not suppose there is a single winner, and that is precisely what makes this comparability attention-grabbing. Each chatbots persistently delivered high-quality outcomes, however they excelled in numerous areas.
I might select Grok if my work relied on researching present occasions, monitoring trade developments, or exploring quickly altering subjects. Its stay internet analysis, broader supply discovery, and conversational method made it really feel extra like a analysis accomplice than a conventional chatbot.
I might select Claude if I wanted an AI assistant for writing, structured reasoning, doc evaluation, or refining complicated concepts. It produced a extra participating writing pattern and clearly organized the report findings, whereas additionally finishing the doc evaluation job and including sensible suggestions.
In the end, the higher selection comes all the way down to the type of work you do most frequently, not which chatbot has the longest function record.
Need to evaluate extra main AI fashions earlier than making your resolution? Discover the most recent rankings, evaluations, and have comparisons for massive language fashions (LLMs) on G2.