On this article, you’ll study the conceptual and sensible variations between retrieval and reminiscence in agentic AI methods, and the best way to mix each successfully.
Subjects we are going to cowl embody:
- What separates retrieval from reminiscence, and why the excellence issues for long-running brokers.
- How retrieval pipelines and reminiscence methods are every constructed, illustrated with a concrete labored instance.
- Methods to mix retrieval and reminiscence right into a single, efficient agent structure.
Introduction
An AI agent that may’t keep in mind its earlier interactions isn’t very useful. Each massive language mannequin has a hard and fast context window, and as soon as a dialog, a set of software outputs, or a pile of retrieved paperwork grows previous that restrict, one thing needs to be dropped, summarized, or fetched contemporary. Builders constructing long-running brokers run into this continuously. The agent re-asks questions it already answered, contradicts choices it made earlier, or fails to acknowledge {that a} doc it wants even exists.
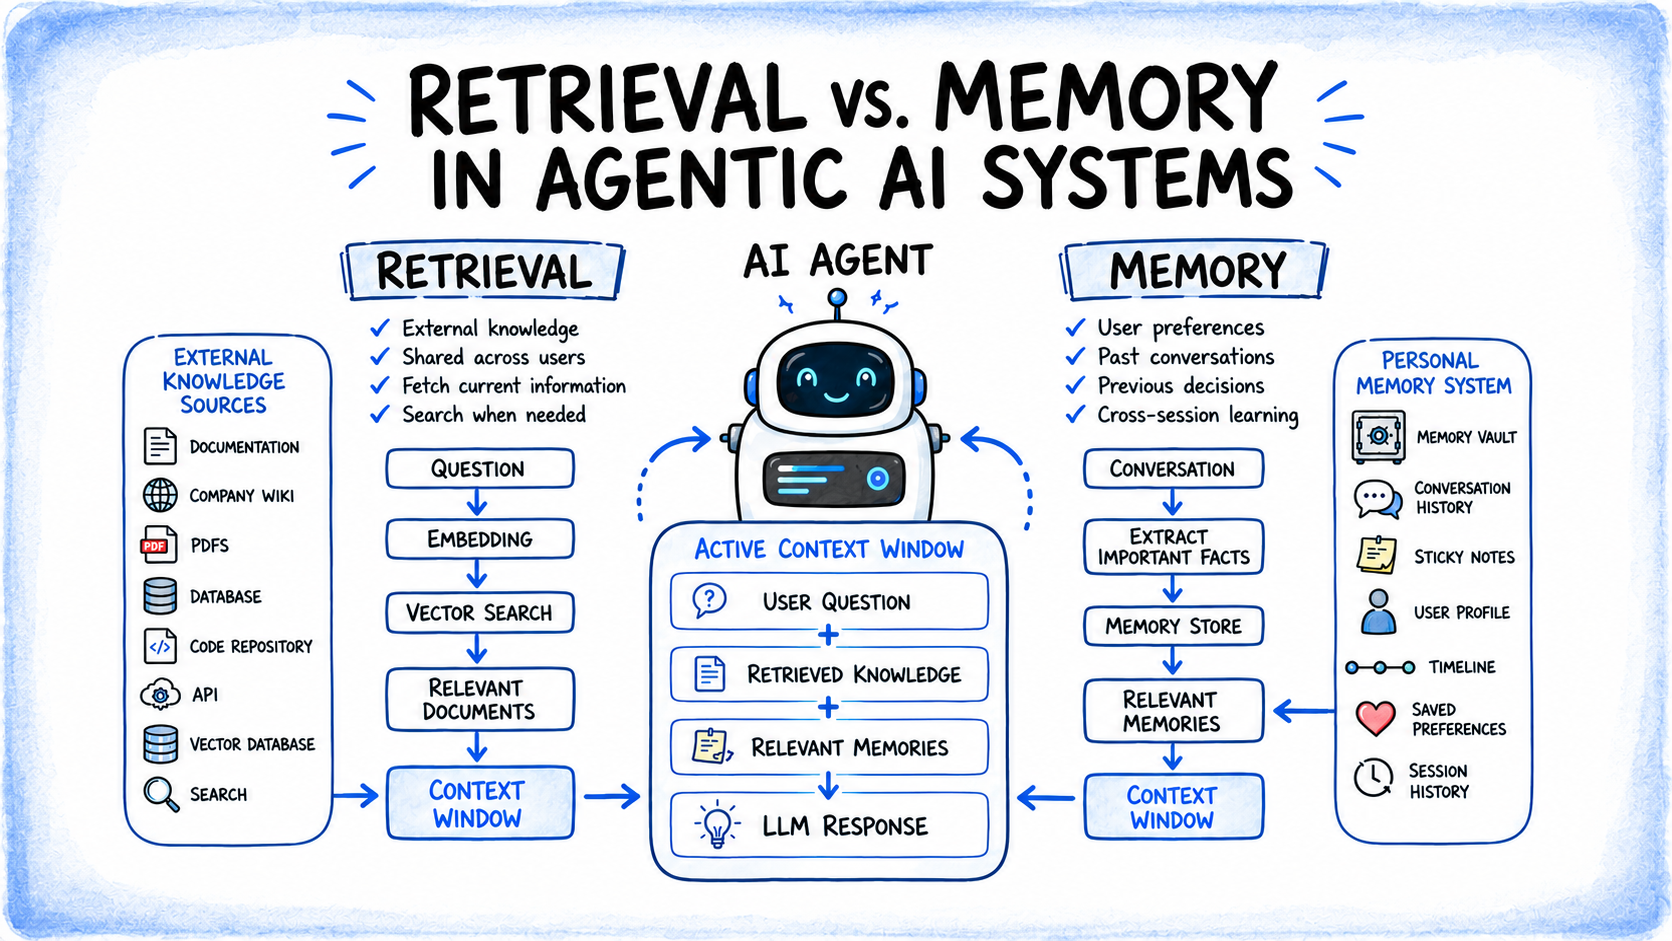
Retrieval and reminiscence are the 2 mechanisms that handle this, they usually remedy completely different halves of the issue. Retrieval pulls in outdoors data the mannequin was by no means skilled on and shouldn’t have to hold by default, equivalent to documentation, code, and database data. Reminiscence persists what the agent itself has discovered or completed, throughout a session or throughout many, so it isn’t ranging from zero each time. Complicated the 2, or constructing just one, is the place loads of agent architectures break down. This text covers:
- What separates retrieval from reminiscence at a conceptual degree
- How a retrieval pipeline and a reminiscence system are every constructed, with a labored instance
- A side-by-side comparability of the 2
- Methods to mix each right into a single, efficient agentic system
We begin with why the cut up exists within the first place.
Understanding Why Context Forces a Cut up
A context window is the full set of tokens the mannequin can see without delay: system immediate, dialog historical past, software outputs, something inserted forward of time. It’s finite, and each token in it will get attended to on each ahead go, so merely making the window greater doesn’t scale the way in which it sounds prefer it ought to. Context engineering has emerged because the self-discipline of curating and managing that restricted useful resource, treating it as the complete state obtainable to the mannequin at a given second, not only a place to stuff directions.
Provided that constraint, an agent has two sorts of data it wants however can’t preserve completely in context:
- Data that exists outdoors the mannequin and out of doors the present dialog, equivalent to a data base, a codebase, or a set of coverage paperwork. That is what retrieval handles.
- Data the agent generated or discovered itself, that should outlive the present context window, equivalent to a call made ten turns in the past or a reality a few particular person. That is what reminiscence handles.
Each get applied with comparable instruments: embeddings, vector search, structured shops. The important thing distinction is what they retailer and the place the data comes from. Retrieval searches a corpus outdoors the agent, whereas reminiscence shops data from the agent’s personal interactions and previous actions.
Defining Retrieval in Agentic Programs
Retrieval is how an agent solutions “what does the world learn about this that I don’t have in my weights or my present context.” The commonest implementation is retrieval-augmented era, or RAG:
- Supply paperwork get chunked into passages sufficiently small to be helpful.
- Every chunk is transformed into an embedding and saved in a vector index.
- At question time, the incoming query is embedded the identical manner, and the index returns the closest matches.
- These matches get inserted into the immediate alongside the person’s query.
This sample sometimes runs on managed datastores with an orchestration layer that ties the retrieval step into the remainder of the agent’s reasoning — the strategy behind most retrieval-augmented era architectures in manufacturing as we speak. The corpus itself is shared — each person asking about the identical product documentation hits the identical index — and it’s refreshed by itself schedule, unbiased of any particular person dialog.
Defining Reminiscence in Agentic Programs
Reminiscence is how an agent solutions “what have I already discovered or completed that I would like to hold ahead.” It splits into two layers that behave in another way:
- Quick-term reminiscence is the operating session state: the dialog up to now, plus something the agent has written to a scratchpad in the course of the present job. It’s low cost, and it disappears when the session ends.
- Lengthy-term reminiscence persists throughout classes. It has to reply a tougher query than retrieval does: not simply “what’s related,” however “what’s value conserving within the first place.”
Some agent reminiscence methods robotically extract helpful information, preferences, and context from conversations and retailer them for later use. Firstly of a brand new session, the agent can question that reminiscence very similar to it might question a retrieval index, however the outcomes are particular to a person, job, or agent fairly than a shared doc corpus. When designing this layer, groups can discover completely different agent reminiscence methods and agent reminiscence frameworks relying on what they should retailer and retrieve.
A fast labored instance makes the cut up concrete. A buyer messages a assist agent a few delayed order.
For a delayed order, the agent first checks its reminiscence for the client’s earlier historical past. It finds a notice from three weeks in the past saying they like electronic mail follow-up and {that a} comparable transport difficulty was resolved with a partial refund. That’s reminiscence, as a result of it comes from the agent’s file of this particular buyer.
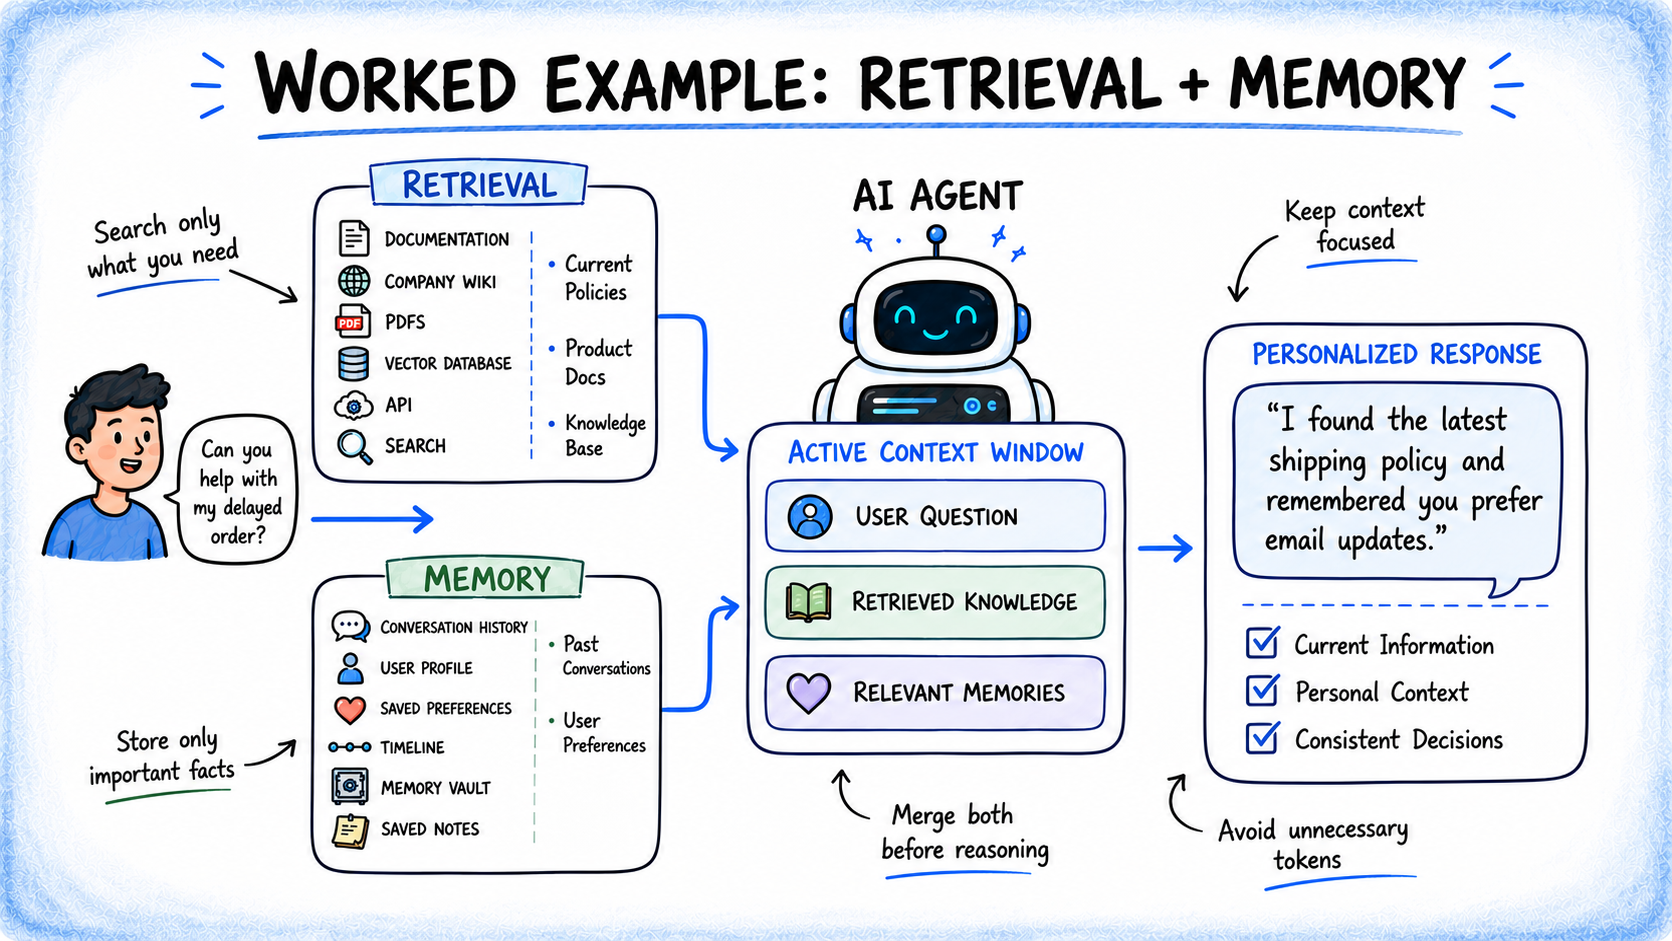
The agent then wants the present transport coverage, which modified final month, so it searches the corporate’s documentation and retrieves the related part. That’s retrieval, as a result of the data comes from an exterior supply and applies to all prospects. Each outcomes are added to the identical immediate, however they reply completely different questions.
Evaluating Retrieval and Reminiscence
Laid out facet by facet, the variations between retrieval and reminiscence are simpler to see at a look:
| Dimension | Retrieval | Reminiscence |
|---|---|---|
| Supply of data | Exterior corpus the agent didn’t create | The agent’s personal previous interactions or reasoning |
| Scope | Shared throughout all customers and classes | Particular to a person, job, or session |
| What it solutions | “What does the world learn about this?” | “What have I already discovered or completed?” |
| Freshness mechanism | Re-index the corpus on a schedule or on write | Consolidate, replace, or expire saved information |
| Typical failure mode | Stale or lacking paperwork within the index | Contradictory or outdated information a few person |
| Price sample | Learn-heavy; one lookup per question | Learn and write; extraction runs after each interplay |
The failure modes listed within the desk above clarify why an agent constructed with solely one of many two tends to interrupt in predictable methods, and why most working methods find yourself needing each.
Combining Retrieval and Reminiscence into an Efficient System
An agent with retrieval however no reminiscence re-derives the identical conclusions each session and might’t personalize something. An agent with reminiscence however no retrieval is aware of its personal historical past however has no approach to floor itself in something outdoors that historical past; it might’t reply questions on a coverage that modified after its coaching knowledge ended. Getting the mixture proper comes down to some issues:
- Filtering issues greater than window dimension. Including extra retrieved paperwork or reminiscence entries doesn’t essentially enhance solutions. Past a degree, further context could make solutions worse as a result of the mannequin has to course of and weigh each extra token. Small, focused searches are sometimes more practical than one broad search and might preserve retrieval token-efficient.
- Staleness works in another way for retrieval and reminiscence. A retrieval index turns into stale when the underlying paperwork change with out being re-indexed. Reminiscence turns into stale when details about a person adjustments — equivalent to a choice or plan — however the saved reality isn’t up to date or eliminated.
- Reminiscence provides a write value. Retrieval normally entails wanting up data when the agent wants it. Reminiscence additionally requires deciding what data is value saving after an interplay, which may add mannequin calls and processing time. This extraction is commonly dealt with asynchronously so it doesn’t decelerate the agent’s response.
- The 2 sources must be merged fastidiously. Retrieval and reminiscence can return data that overlaps or conflicts. The agent wants clear guidelines for deciding how a lot weight to provide every supply and the best way to use each in the identical context.
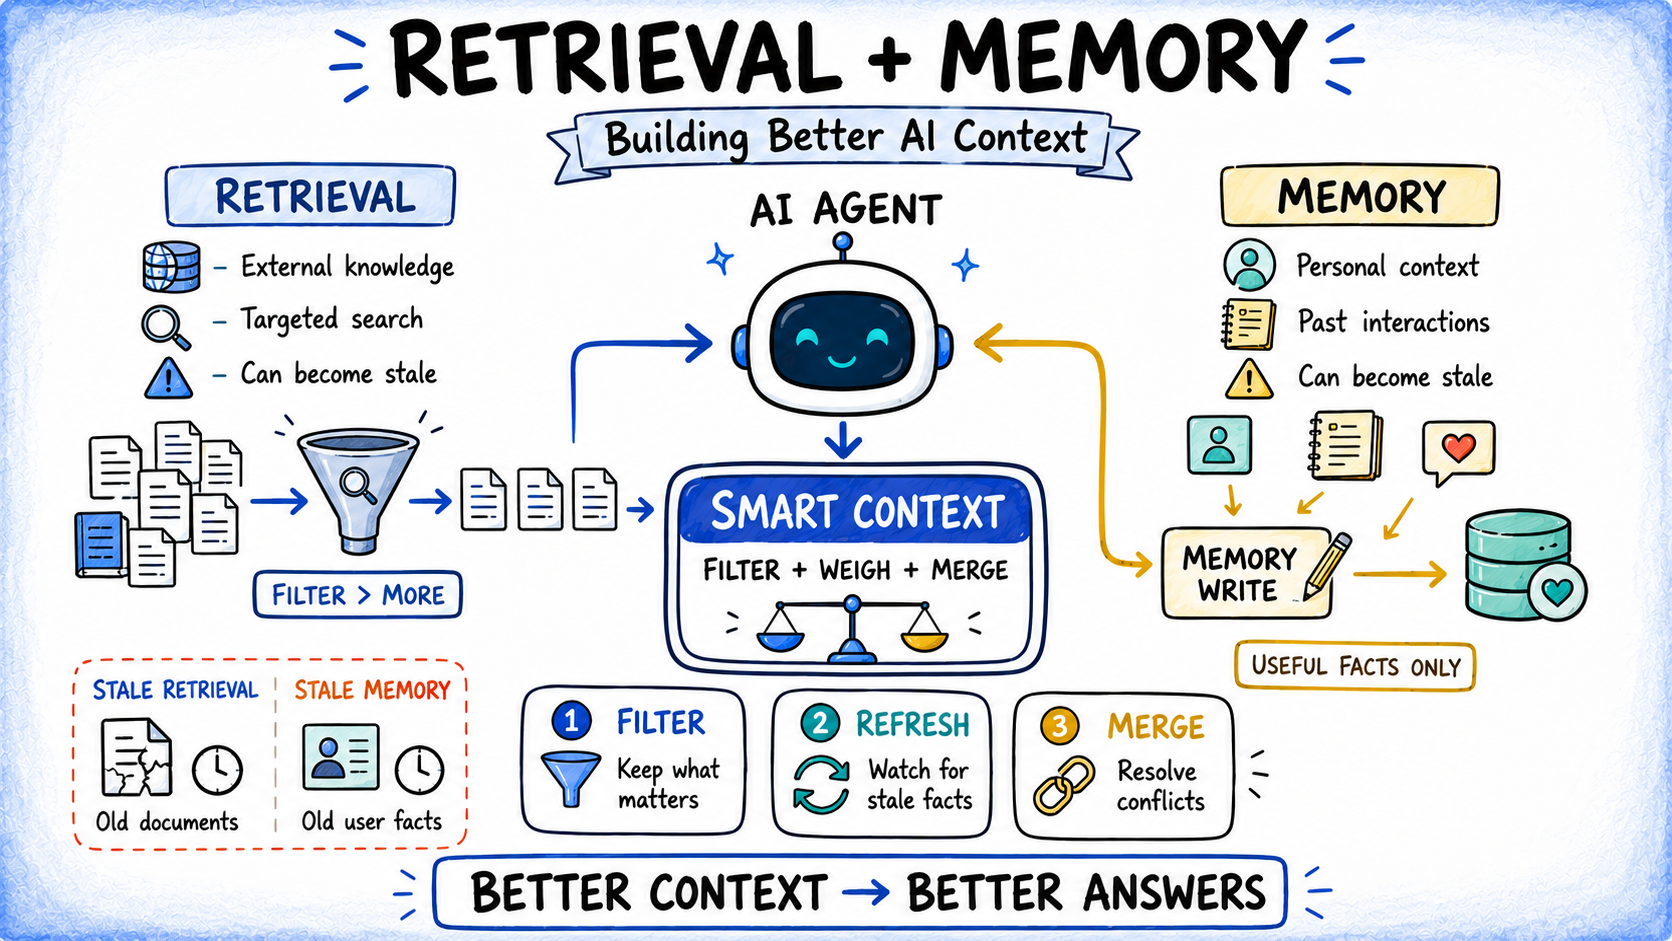
The design work for retrieval and reminiscence comes right down to deciding what belongs in every, how aggressively to prune each, and the way they arrive collectively right into a single immediate with out handing the mannequin tokens it doesn’t want.
Abstract
Retrieval and reminiscence remedy completely different issues in long-running agent methods. Retrieval brings in exterior data the agent wants for the time being, equivalent to documentation, insurance policies, code, or database data. Reminiscence carries ahead data from earlier interactions, equivalent to choices, preferences, and user-specific context. The excellence issues as a result of the 2 methods have completely different scopes, freshness considerations, and failure modes. Retrieval depends upon conserving exterior sources updated, whereas reminiscence depends upon deciding what’s value storing and when saved data is now not legitimate.
The best agent architectures use each. They filter what enters the context, preserve data moderately contemporary, and merge retrieved data with related reminiscence as an alternative of treating both as an entire file of every thing the agent must know.
The objective, subsequently, is to provide the agent the context it wants, when it wants it, with out carrying pointless data.