On this article, you’ll discover ways to match an LLM inference optimization method to the precise bottleneck in your workload by working via a six-question choice tree.
Matters we’ll cowl embrace:
- What every main inference optimization method, from quantization to prefill-decode disaggregation, assumes about your workload.
- How one can work via a call tree that routes you to the correct method based mostly in your mannequin and visitors.
- How the strategies evaluate on trade-offs, and which signs present {that a} chosen method isn’t working.
Introduction
LLM inference will get gradual and costly as visitors grows. Requests queue behind lengthy generations, GPU reminiscence fills with cached consideration state, and the {hardware} spends a lot of its time ready on reminiscence reads.
Inference optimization is the set of strategies that assist right here. Some strategies goal reminiscence, some goal compute, and a few goal how requests are scheduled in opposition to one another. Every method assumes one thing particular about your workload, so the correct alternative relies on which assumptions maintain for yours. This text covers:
- What every main inference optimization method assumes about your workload
- A call tree that routes you to a way
- How the strategies evaluate on latency, throughput, and implementation price
- The signs that present a way isn’t working
We begin with what every method assumes.
What Every Inference Optimization Method Assumes
LLM inference has many optimization strategies, however each addresses a special sort of bottleneck. Earlier than utilizing one, it helps to grasp the workload it’s designed for.
| Method | What It Assumes |
|---|---|
| Quantization / sparsity / distillation | The mannequin itself is simply too giant for the {hardware} or the latency funds, and shrinking it’s price some accuracy danger |
| Prefix caching | Many requests share an equivalent beginning sequence of tokens, so recomputing that prefix is wasted work |
| Steady (in-flight) batching | Requests arrive concurrently with unpredictable output lengths, and ready for the slowest one in a batch wastes the GPU |
| PagedAttention | KV cache reminiscence is fragmented or over-provisioned, capping batch dimension beneath what the {hardware} may in any other case maintain |
| Speculative decoding | Decode is the bottleneck, tokens are generated separately, and a less expensive draft mannequin can guess a number of of them appropriately |
| Prefill-decode disaggregation | Prefill and decode are contending for a similar GPU, and that competition is hurting each time-to-first-token and inter-token latency directly |
| Tensor / pipeline parallelism | The mannequin doesn’t slot in a single gadget’s reminiscence, or per-device compute is the ceiling on throughput |
| KV cache offloading | Helpful cache entries are being evicted too early as a result of GPU reminiscence can’t maintain every thing you’d prefer to maintain |
| Offline batch inference | Requests don’t want an interactive response, and whole throughput outweighs per-request latency |
Select the method based mostly on the bottleneck in your workload to keep away from pointless complexity.
Working Via a Resolution Tree to Select a Method
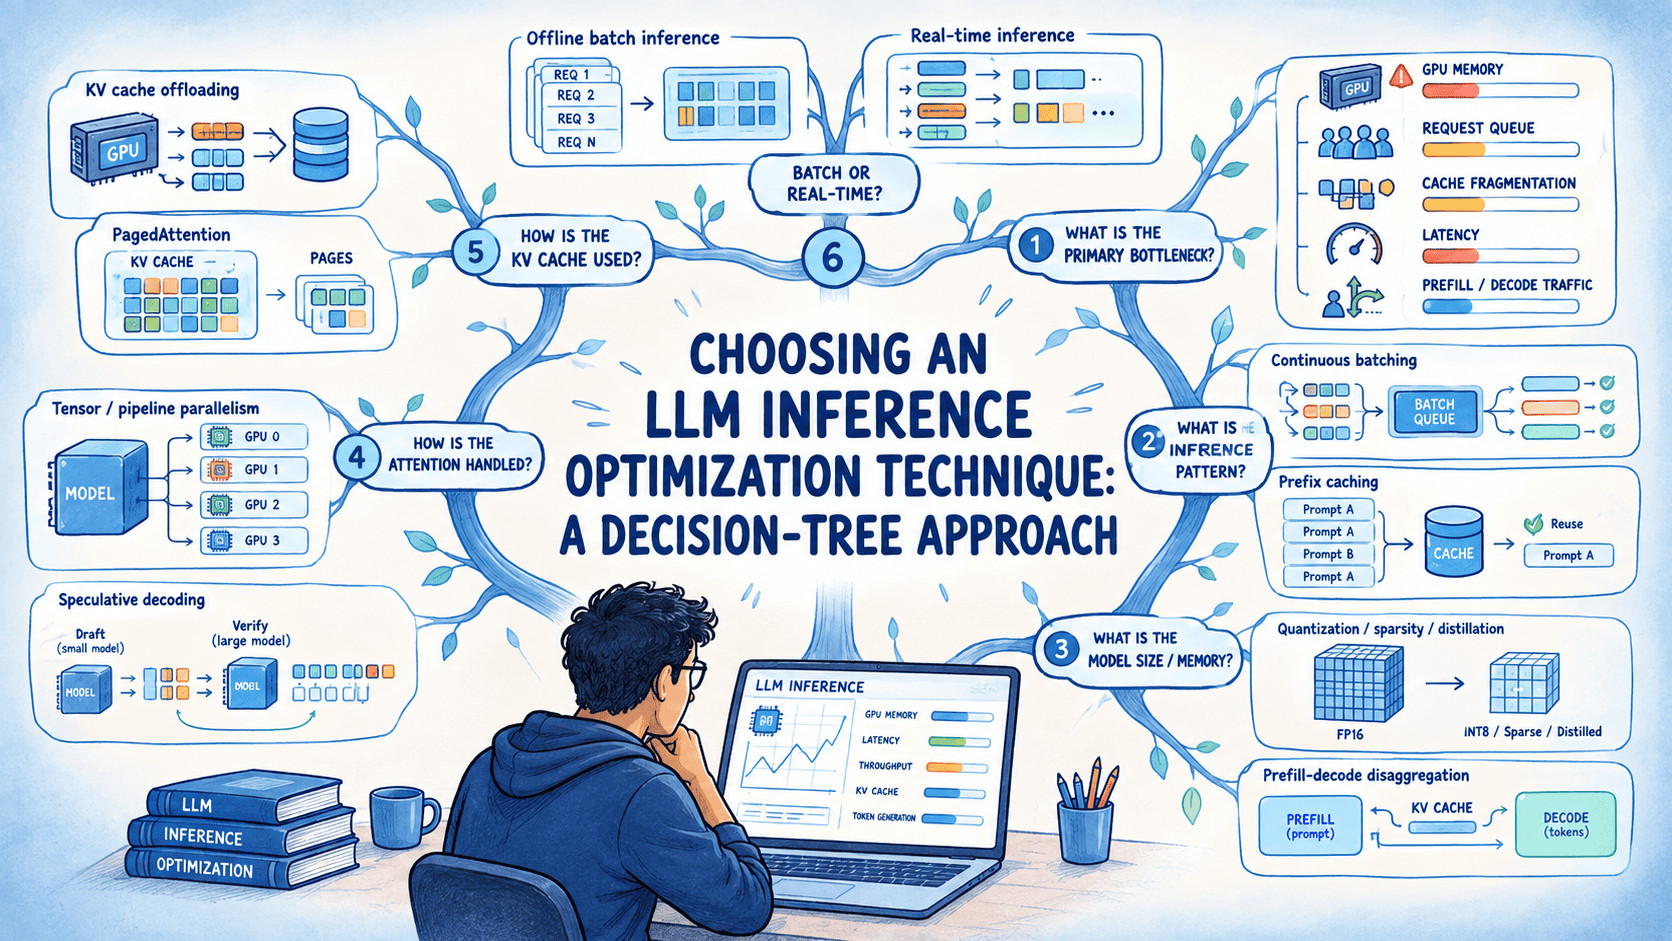
The tree beneath has six branching questions. Every one narrows the sector based mostly on a selected property of your mannequin or your visitors. Each query ends the identical method: a direct reply if the situation holds, and a pointer to the following query if it doesn’t.
Query 1: Does the Mannequin Match Comfortably on Your Goal {Hardware}?
Earlier than transferring on to the serving stack, verify whether or not the mannequin itself is the issue. A mannequin that hardly matches in GPU reminiscence leaves virtually no room for KV cache, which caps your batch dimension regardless of how good your scheduler is.
If the mannequin is simply too giant, or inference is compute-bound even at batch dimension one, begin with model-level compression:
- Quantization reduces the precision of weights and activations.
- Structured sparsity removes much less necessary weights to scale back computation.
- Distillation trains a smaller mannequin to imitate a bigger mannequin.
These strategies are principally impartial of the serving stack, and chances are you’ll wish to take into account them first as a result of they decide how a lot {hardware} capability stays.
If the mannequin already matches with headroom to spare, transfer to Query 2.
Query 2: Do Your Requests Share Repeated Immediate Construction?
Chat functions resend the total dialog historical past on each flip. Agent frameworks reuse the identical system immediate throughout 1000’s of calls. Retrieval-augmented technology (RAG) pipelines usually prepend the identical directions to completely different retrieved contexts.
If a significant share of your visitors has an equivalent prefix, whether or not that’s a system immediate or a rising chat historical past, prefix caching is the highest-leverage method obtainable. It skips recomputing the KV cache for tokens the mannequin has already processed, and the beneficial properties compound as conversations get longer.
⚠️ Prefix caching solely works when the shared prefix matches precisely, character for character. Put secure, reusable content material first and variable content material on the finish of the immediate.
In case your prompts are principally distinctive with little shared construction, transfer to Query 3.
Query 3: Are Requests Arriving Concurrently With Variable Output Lengths?
A assist chatbot that returns a one-sentence reply and a code assistant that returns 4 hundred strains not often end on the identical time, even when they began collectively. Below naive batching, the entire batch waits on the slowest request.
In case your visitors mixes brief and lengthy generations and arrives in overlapping bursts, steady batching fixes the idle time this creates. Completed sequences depart the batch instantly, permitting new requests to begin with out ready for a batch boundary. Most serving engines allow this by default.
In case your visitors is already well-batched and GPU idle time just isn’t an issue, transfer to Query 4.
Query 4: Is KV Cache Fragmentation Limiting Your Batch Measurement?
Some engines reserve a set, contiguous block of reminiscence per request sized for the utmost doable sequence size, even when most requests are a lot shorter. That reserved area sits unused for the lifetime of the request and blocks different requests from utilizing it.
If KV cache is losing reminiscence or limiting batch dimension, PagedAttention will help. It splits the cache into fixed-size pages, permitting reminiscence to be allotted in smaller chunks as an alternative of huge contiguous blocks. Most trendy serving engines already assist it, so verify whether or not it’s enabled earlier than including new configuration.
If reminiscence just isn’t the constraint, transfer to Query 5.
Query 5: Is Per-Token Decode Latency the Metric You’re Focusing On?
In case your objective is quicker token streaming for every consumer quite than greater general throughput, take into account speculative decoding.
A smaller draft mannequin predicts a number of tokens forward, and the primary mannequin verifies them in a single go. When the draft mannequin predicts appropriately, a number of sequential decode steps will be accomplished collectively, lowering inter-token latency.
The trade-off is the additional mannequin and verification overhead. For those who don’t have an acceptable draft mannequin or its predictions are accepted too not often, the added complexity could not repay. In that case, transfer to Query 6.
Query 6: Are Prefill and Decode Contending for the Similar GPU at Scale?
That is primarily a production-scale concern as a result of it adjustments the serving structure.
If lengthy prefills are delaying decode requests and hurting each time-to-first-token and inter-token latency, prefill-decode disaggregation can separate the 2 phases onto devoted {hardware}. Prefill nodes course of prompts, then go the KV cache to decode nodes optimized for token technology.
This provides KV-cache switch and routing overhead, so it is sensible solely when the visitors justifies that complexity. For smaller workloads or non-interactive requests, offline batch inference is usually less complicated. If none of those circumstances apply, begin with steady batching and prefix caching.
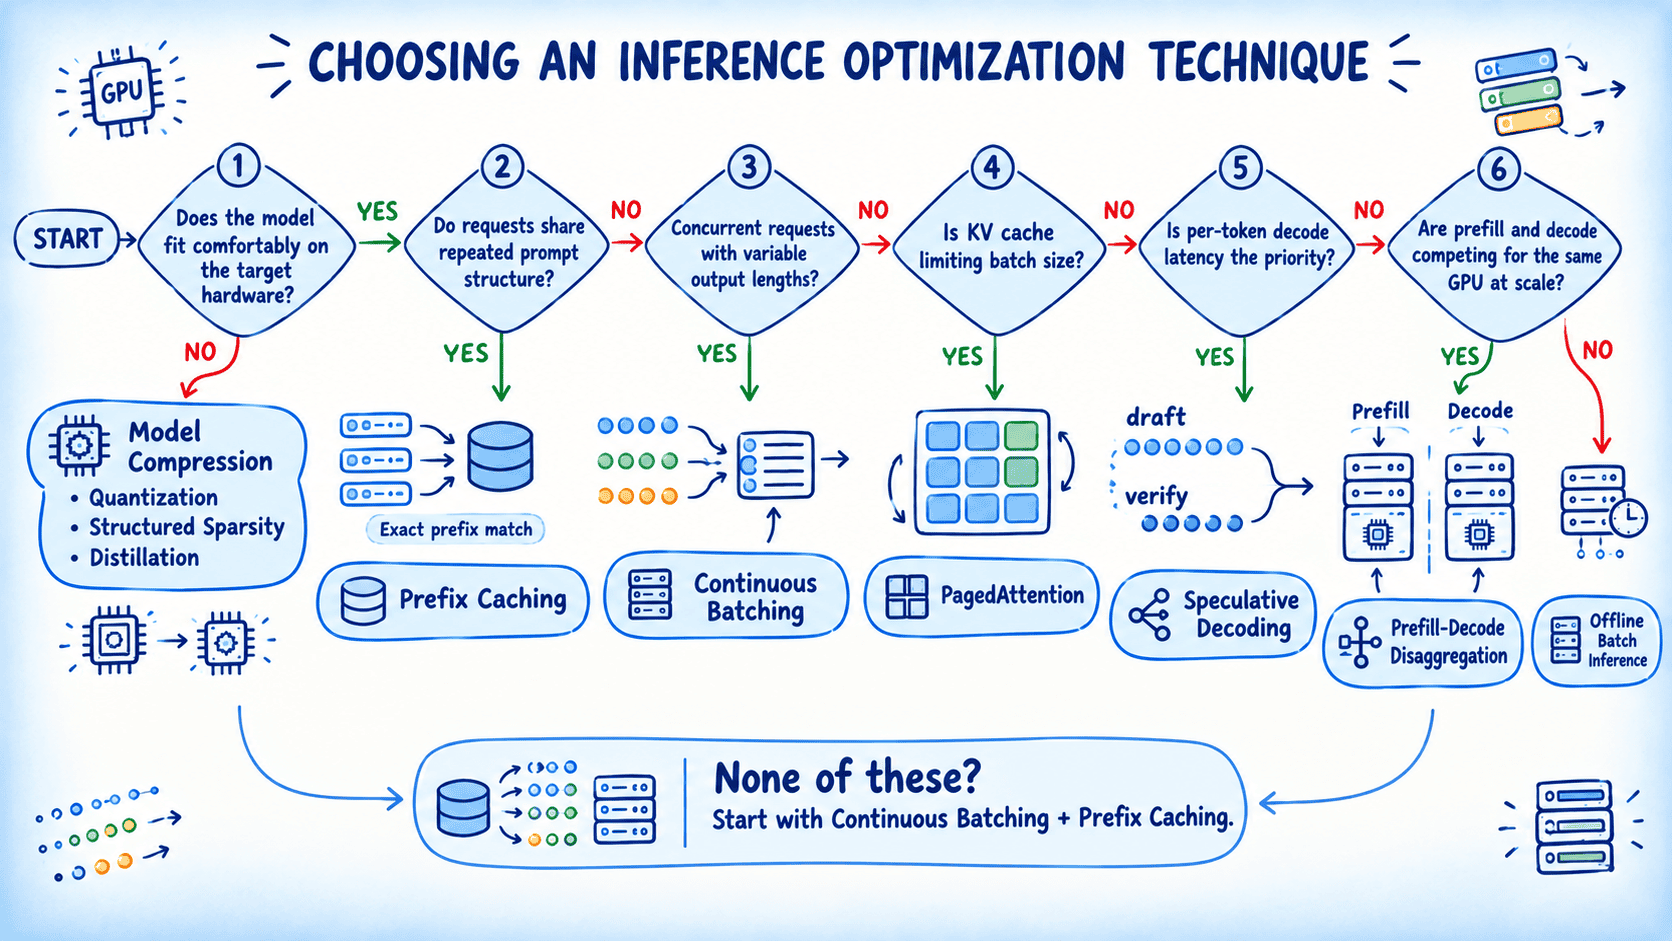
Mapping the Resolution Tree to an Optimization Method
Working via the tree lands you on one of many strategies within the following desk:
| Method | Finest For | Commerce-off |
|---|---|---|
| Quantization / sparsity / distillation | Fashions too giant for the goal {hardware} or latency funds | Some accuracy loss, and quantized activations are tougher to get proper than quantized weights |
| Prefix caching | Chat, brokers, and RAG workloads with repeated immediate construction | Breaks on any character-level mismatch within the shared prefix |
| Steady batching | Concurrent visitors with variable output lengths | Minimal draw back; principally a matter of whether or not it’s enabled |
| PagedAttention | Workloads bottlenecked by KV cache fragmentation | Provides a web page desk layer to consideration computation |
| Speculative decoding | Latency-sensitive single-user technology | Wants a draft mannequin with a fairly excessive acceptance price to repay |
| Prefill-decode disaggregation | Giant-scale visitors the place prefill and decode contend for a similar GPU | Community price of transferring the KV cache between nodes, plus routing complexity |
| Tensor / pipeline parallelism | Fashions that don’t match on a single gadget | Pipeline bubbles and inter-device communication overhead |
| KV cache offloading | Lengthy-context or high-concurrency workloads working out of GPU reminiscence for cache | Fetching offloaded cache again provides latency |
| Offline batch inference | Non-interactive workloads prioritizing whole throughput | Not usable for something with a strict response-time requirement |
Recognizing Frequent Inference Optimization Pitfalls
A way that you just suppose will work could behave fairly in another way in apply. The indicators beneath inform you when that’s occurring and what to verify first.
| Symptom | Probably Trigger | Repair |
|---|---|---|
| Prefix cache hit price is close to zero regardless of repeated prompts | Non-deterministic serialization, or dynamic content material positioned early within the immediate | Entrance-load static content material and repair key ordering in serialized context |
| Batch dimension received’t develop even with reminiscence to spare | PagedAttention isn’t enabled, or web page dimension is misconfigured | Test the serving engine’s batching and cache flags instantly quite than assuming defaults |
| Speculative decoding is slower than plain decoding | Draft mannequin’s acceptance price is simply too low for the goal mannequin | Decide a draft mannequin nearer in conduct to the goal, or drop speculative decoding for this workload |
| Disaggregation made latency worse, not higher | Workload is simply too small, or most requests are brief and cache-heavy | Fall again to native prefill and revisit disaggregation solely previous an outlined visitors threshold |
| Throughput beneficial properties from quantization didn’t present up | Solely weights have been quantized whereas activations stayed at full precision, and the GPU nonetheless converts again earlier than compute | Profile the place time is spent earlier than assuming quantization alone will repair throughput |
If a way persistently underperforms, verify its underlying assumption earlier than including extra complexity.
Wrapping Up
Selecting an inference optimization method begins with figuring out your bottleneck. Mannequin dimension, immediate overlap, visitors concurrency, reminiscence fragmentation, and the steadiness between throughput and per-user latency every level towards a special reply, and most programs will want a mix of some of those quite than counting on only one.
For those who’re taken with studying extra, chances are you’ll discover The Roadmap to Mastering LLM Inference Optimization helpful.
Comfortable studying!
About Bala Priya C
Bala Priya is a developer, educator, and technical author based mostly in India. She writes about programming, information science, machine studying, and AI, with a concentrate on making complicated technical concepts sensible and approachable.
With over 5 years of expertise in technical writing, she creates tutorials, how-to guides, and deep dives that assist builders construct, clear up issues, and perceive complicated technical ideas. Her technical pursuits embrace LLM functions, agentic AI, graph algorithms, pc imaginative and prescient, explainable AI, and ML programs.
When she’s not writing or coding, Bala is often studying traditional literature, epic fantasy, or speculative fiction. She additionally enjoys speaking about books, studying new issues, and sharing what she learns with the developer neighborhood.